updates

News

2026-11-09

Anthropic: Claude can design electronic prototypes from start to finish

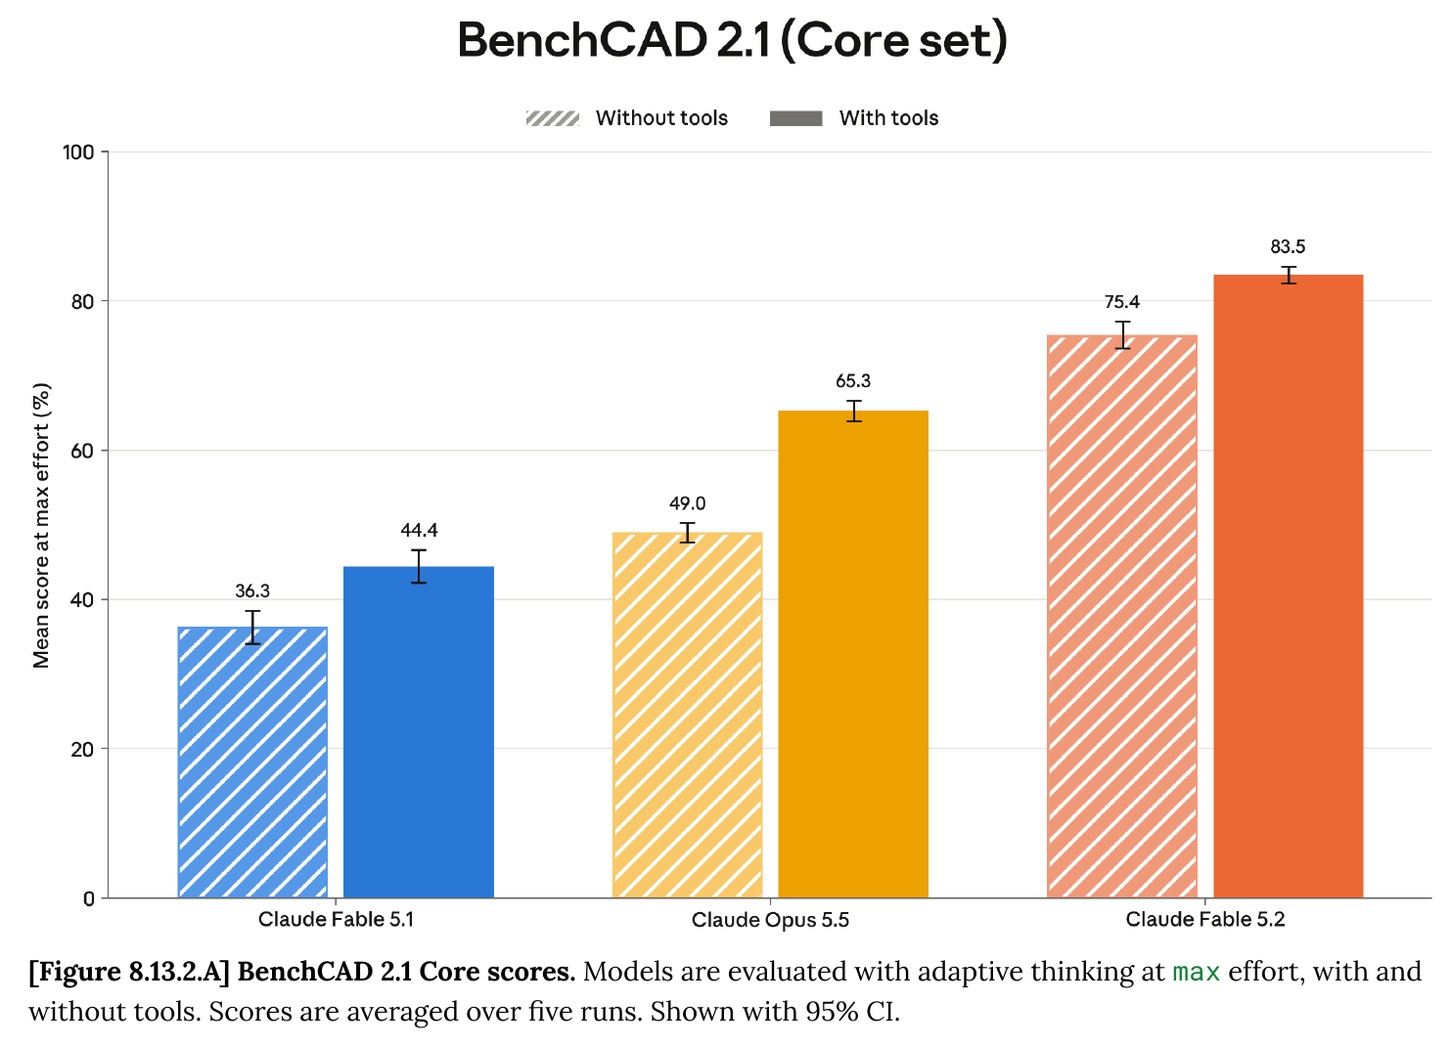
In a new research post, Anthropic and Diode Computers show Claude Fable 5.2 designing three working electronic prototypes, a speakerphone, a voice-assistant hub and a handheld pet, from concept to manufactured boards. The post cites BenchCAD 2.1, where Fable 5.2 scores 0.835 with tools, nearly double Claude Fable 5.1.
Anthropic's illustration for the post: a drawn signal trace beside a photo of a circuit board
read the post 2.1 leaderboard
2026-11-09

Claude Fable 5.2 on BenchCAD 2.1: 0.754 with the standard harness, 0.835 with tools

Anthropic's Fable 5.2 system card reports BenchCAD 2.1 Core: at max effort, Claude Fable 5.2 scores 0.754 with the standard 2.1 harness and 0.835 with tools, ahead of Claude Opus 5.5 at 0.490 and 0.653. Congratulations to the Anthropic team!

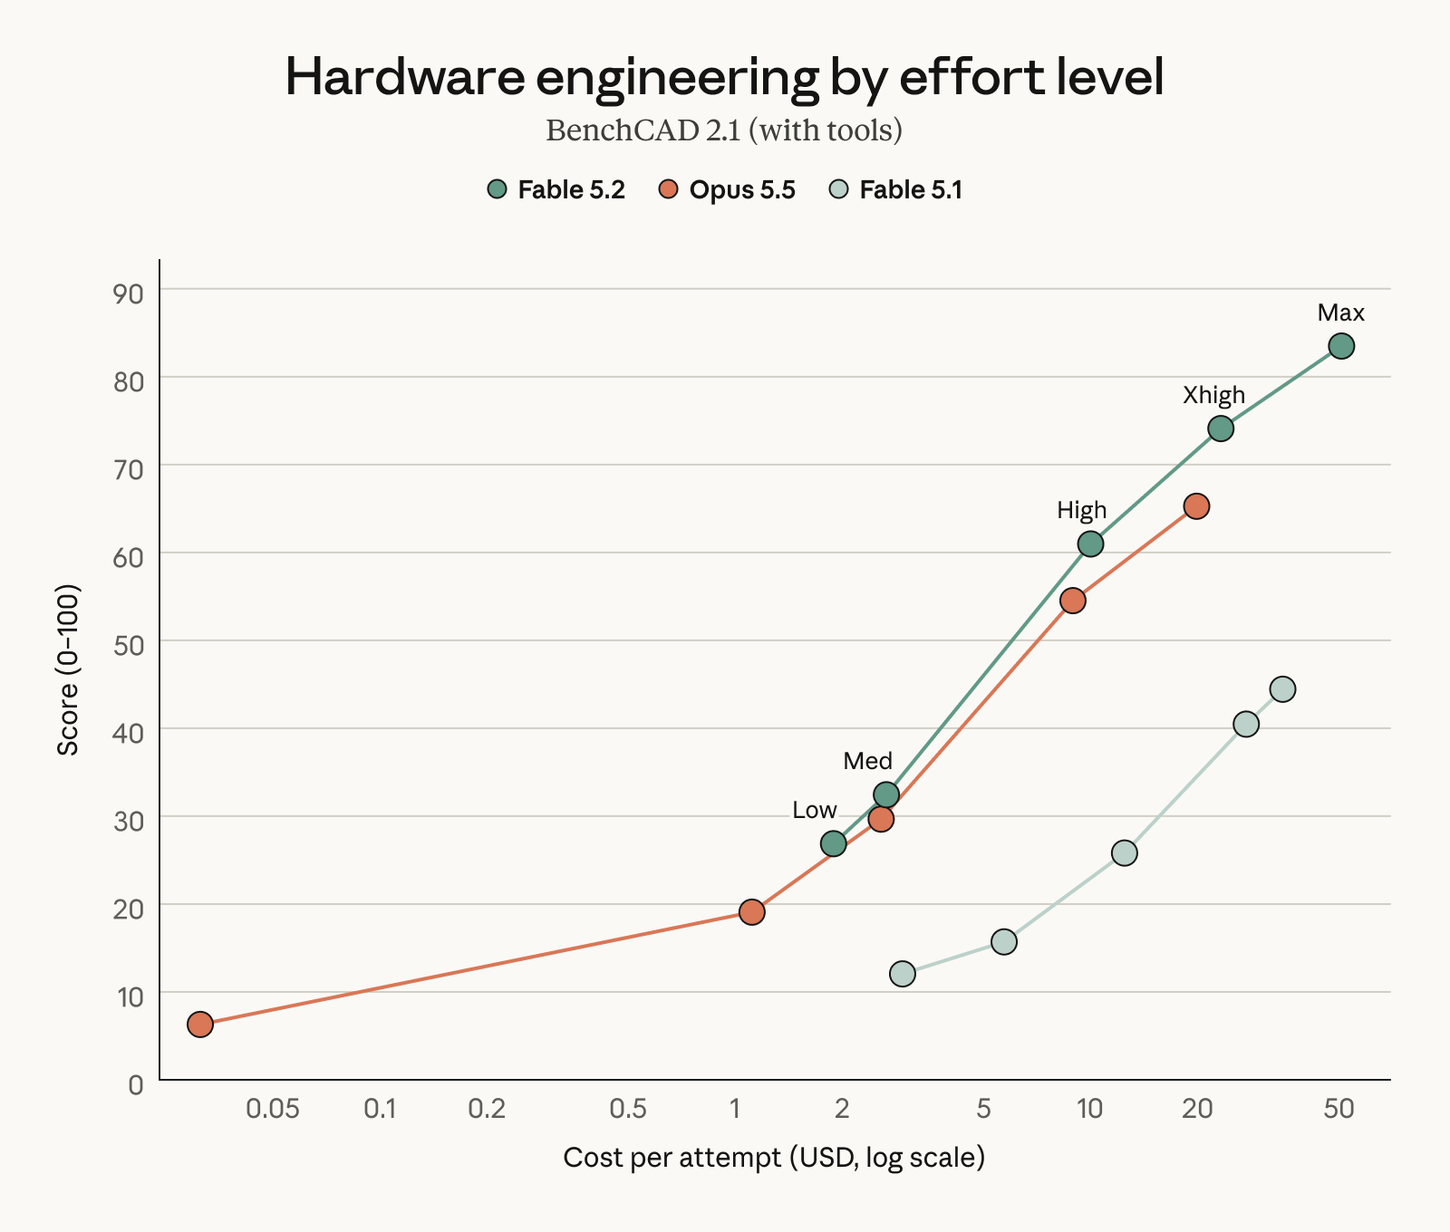
Anthropic's chart, Hardware engineering by effort level, BenchCAD 2.1 (with tools): score against cost per attempt on a log axis. Claude Fable 5.2 rises from about 27 at Low to 83.5 at Max, above Claude Opus 5.5 at every cost from Med up; Claude Fable 5.1 is far lower.

By reasoning effort, with tools, Fable 5.2 matches Opus 5.5 at low cost and pulls ahead from high effort up. At max effort, with and without tools:

Anthropic's chart, BenchCAD 2.1 (Core set): mean score at max effort without and with tools. Claude Fable 5.1 36.3 and 44.4, Claude Opus 5.5 49.0 and 65.3, Claude Fable 5.2 75.4 and 83.5.
read the system card announcement 2.1 leaderboard
2026-11-05

BenchCAD 2.1: a new standard harness for Core, and a track for customized harnesses

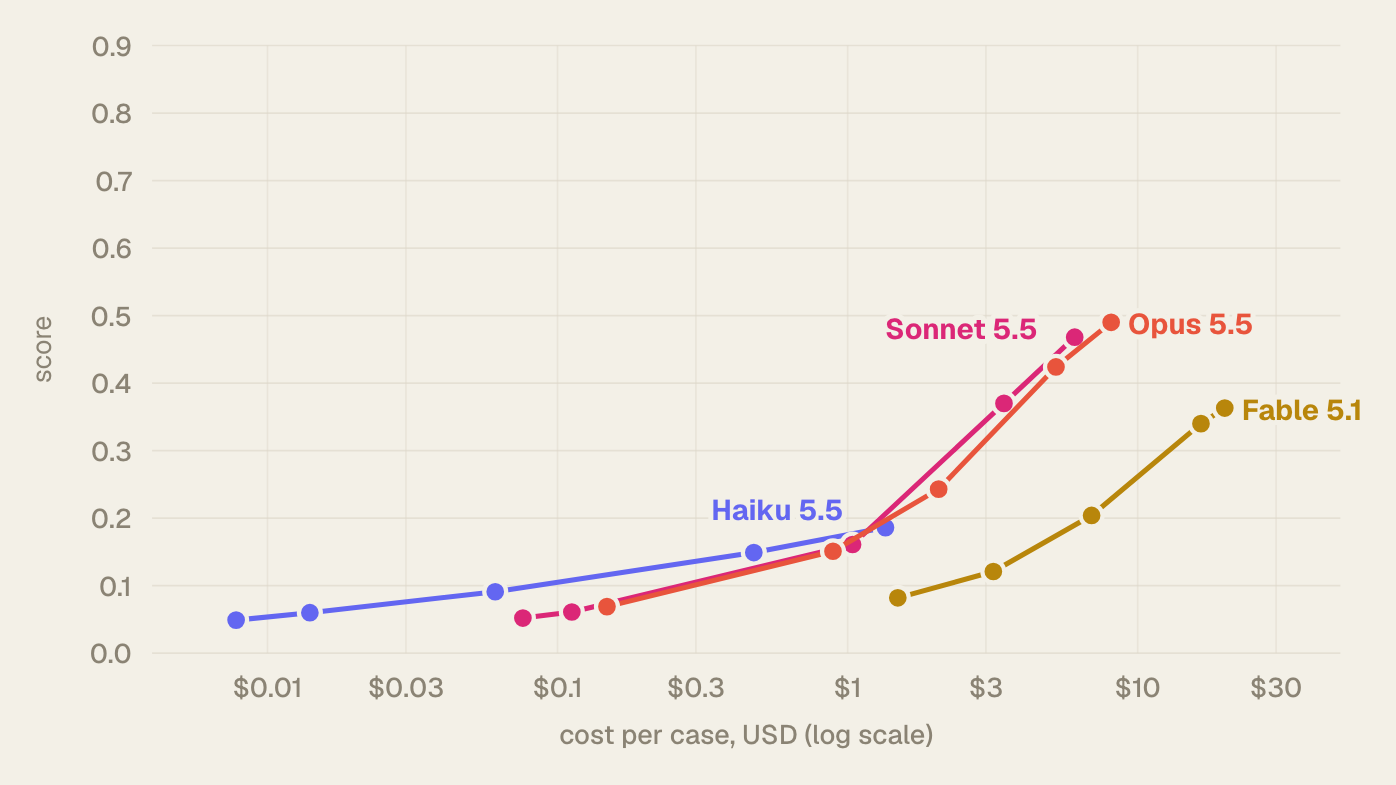
BenchCAD 2.1 gives each Core case 60 rounds and 500,000 output tokens, thinking included, and carries the model's reasoning from round to round. A new track runs Core in a customized harness, such as a lab's own agent, on a board of its own. Anthropic's runs of both are on the leaderboard.

Score on Core against cost per case with the 2.1 harness, run by Anthropic, one point per reasoning effort: Claude Opus 5.5 up to 0.49, Sonnet 5.5 0.47, Fable 5.1 0.36, Haiku 5.5 0.19.
read the post 2.1 leaderboard
2026-11-03

OpenAI on BenchCAD 2.0: a newer internal model scores 0.875

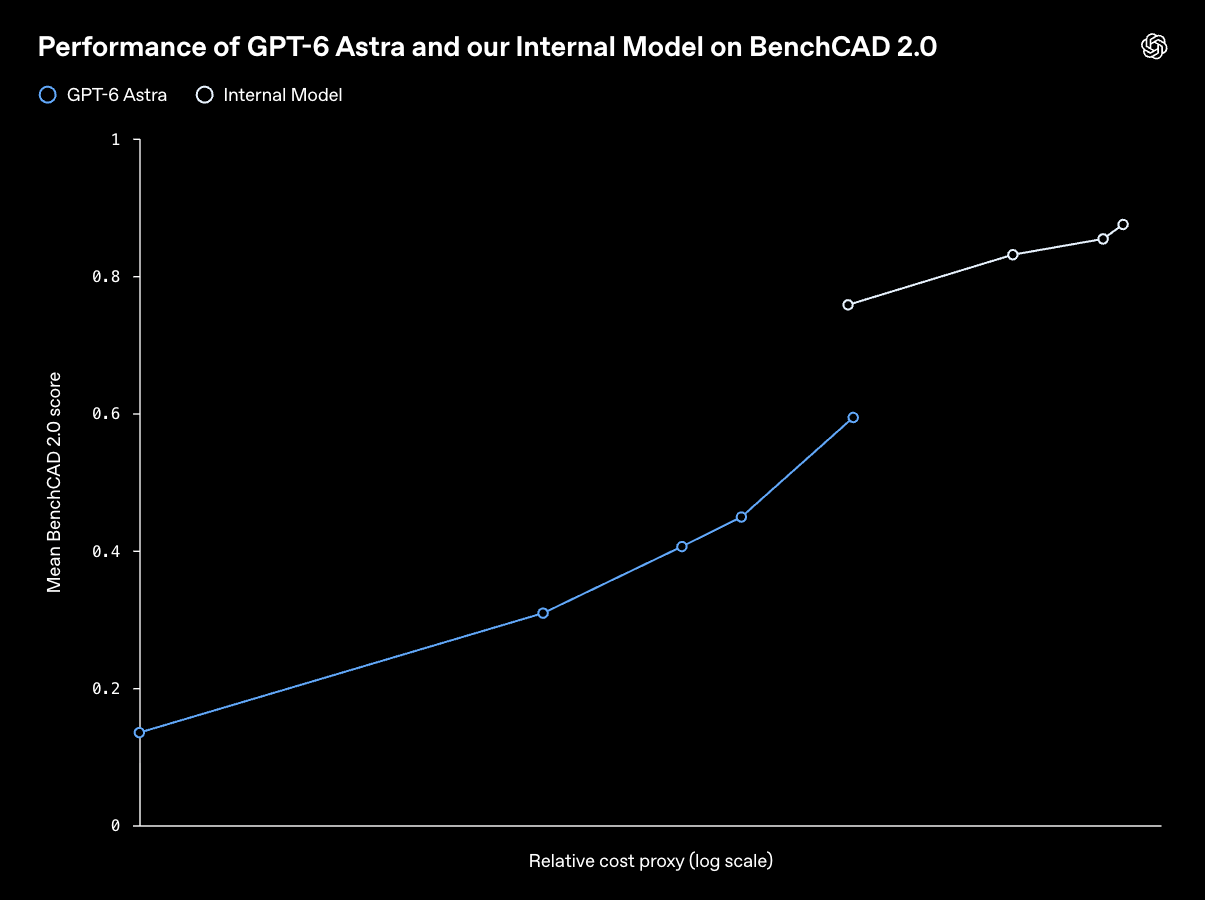
OpenAI's post on AI for physical engineering measures progress with BenchCAD 2.0: a newer internal model averages 0.875, against 0.594 for GPT-6 Astra at its highest reasoning setting, the best score on Core at our launch. Congratulations to the OpenAI team!

OpenAI's chart, Performance of GPT-6 Astra and our Internal Model on BenchCAD 2.0: mean BenchCAD 2.0 score against relative cost on a log scale. GPT-6 Astra rises from 0.135 to 0.594; the internal model runs from about 0.76 to 0.875.

In the chart, the internal model's cheapest setting already scores about 0.76, above Astra's best at about the same cost.

read the post
2026-10-23

Kimi K3.1 Pro on BenchCAD: 0.927 with tools, 0.728 without

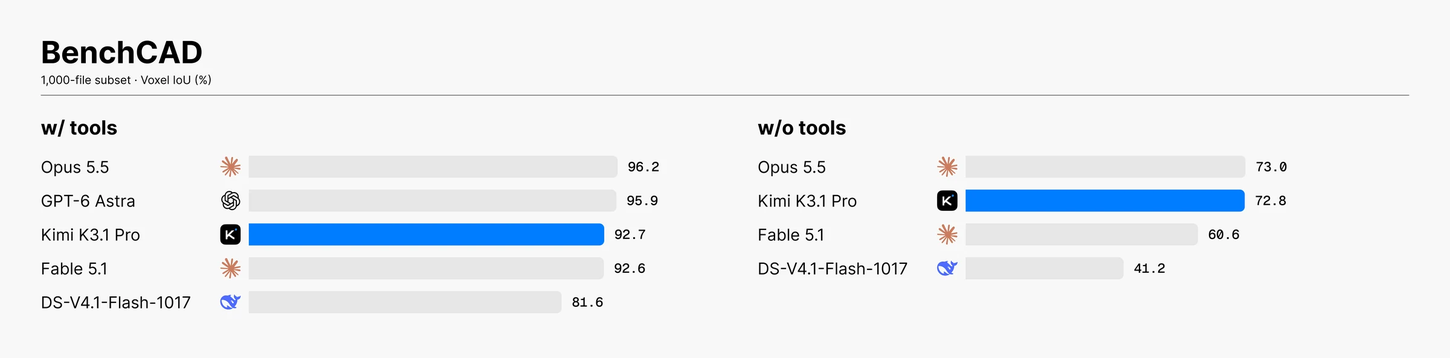
Moonshot's K3.1 Pro launch post reports 0.927 with tools and 0.728 without on a random 1,000-file Vision2Code subset at max effort, first among open models on our leaderboard in both settings and up from 0.367 for Kimi K3 (our re-grade on the full set). Congratulations to the Kimi team!

BenchCAD Vision2Code ranking on 2026-10-23
BenchCAD (1,000-file subset, voxel IoU): with tools, Claude Opus 5.5 96.2, GPT-6 Astra 95.9, Kimi K3.1 Pro 92.7, Claude Fable 5.1 92.6, DeepSeek-V4.1-Flash-1017 81.6; without tools, Claude Opus 5.5 73.0, Kimi K3.1 Pro 72.8, Claude Fable 5.1 60.6, DeepSeek-V4.1-Flash-1017 41.2.
read the launch post
2026-10-12

Introducing BenchCAD 2.0: the best model scores 0.59 on Core

BenchCAD 2.0 tests professional hardware engineering work: parts and assemblies from engineering drawings or rendered views, and board wiring from renders. Five frontier models ran on Core, 100 held-out cases, at every reasoning effort; the best, GPT-6 Astra at max effort, scores 0.59.

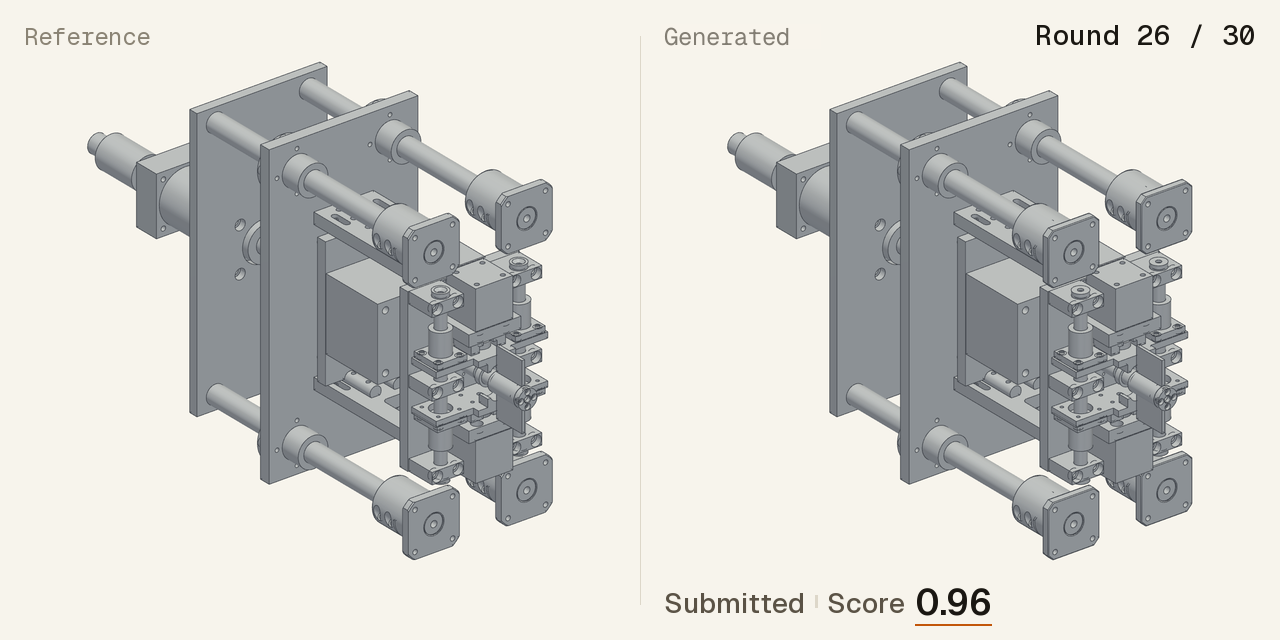
A pneumatic cutting unit from the BenchCAD 2.0 public set: the reference next to a generated answer.
read the post Core access
2026-10-07

Claude Haiku 5.5 on BenchCAD: 0.870 with tools, 0.670 without

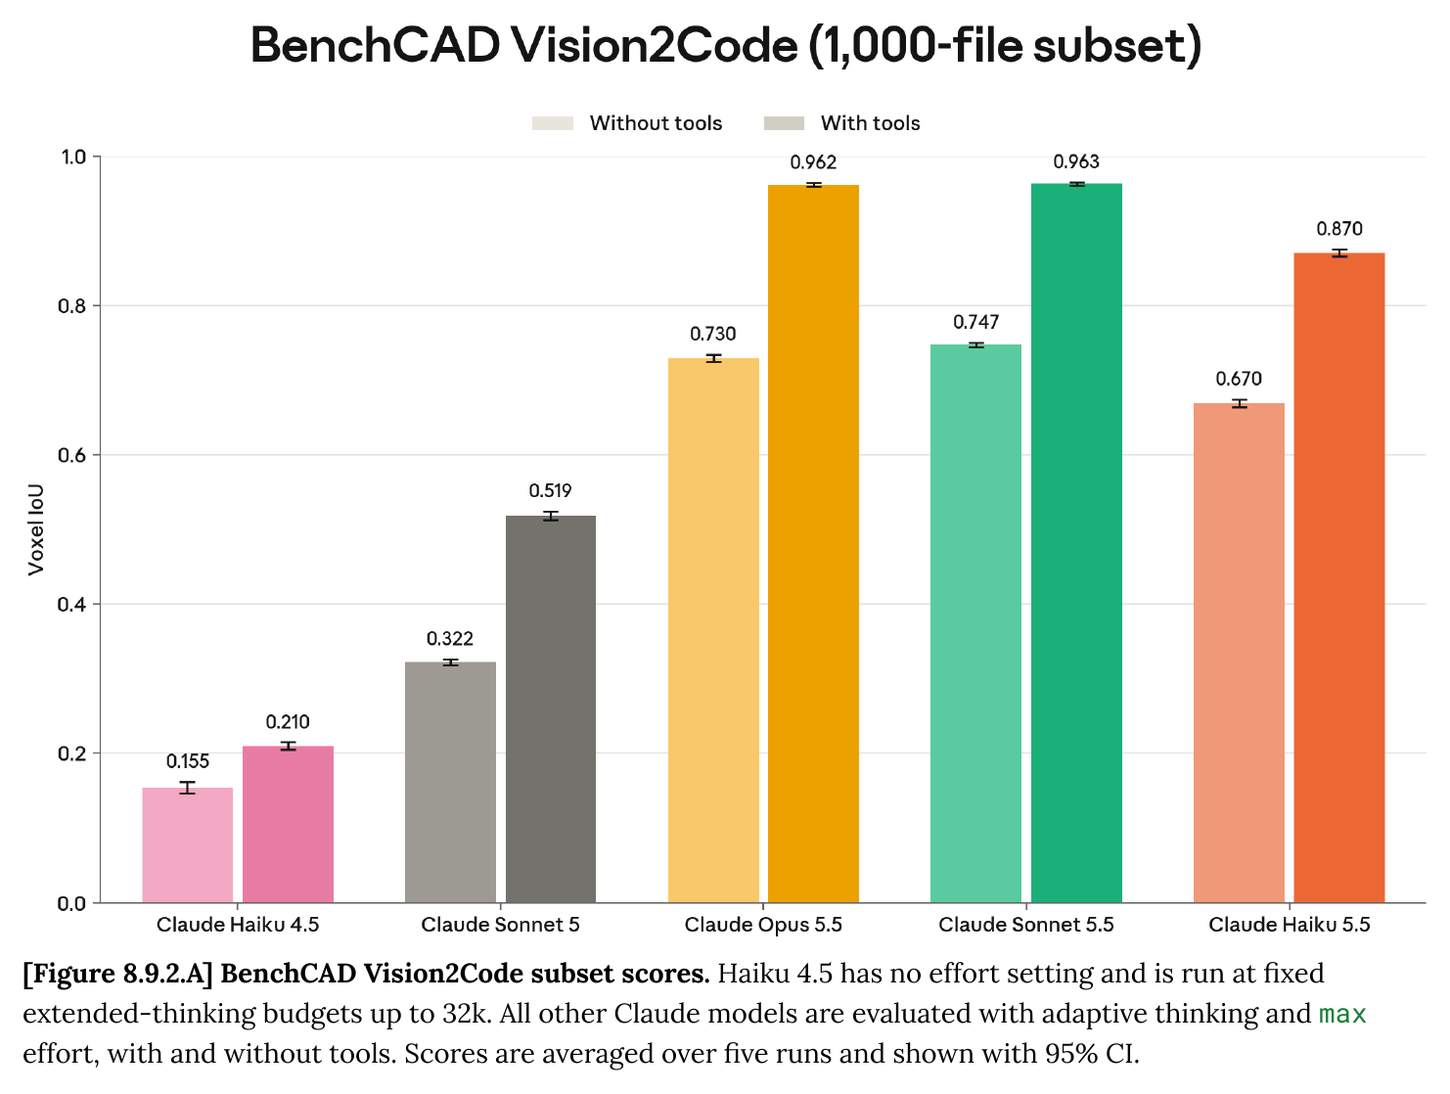
Anthropic's Haiku 5.5 system card reports 0.870 with tools and 0.670 without on the 1,000-file Vision2Code subset, up from 0.210 and 0.155 for Haiku 4.5. Congratulations to the Anthropic team!

BenchCAD Vision2Code ranking on 2026-10-07
BenchCAD Vision2Code (1,000-file subset) voxel IoU, without tools vs with tools: Claude Haiku 4.5 0.155 / 0.210, Claude Sonnet 5 0.322 / 0.519, Claude Opus 5.5 0.730 / 0.962, Claude Sonnet 5.5 0.747 / 0.963, Claude Haiku 5.5 0.670 / 0.870.

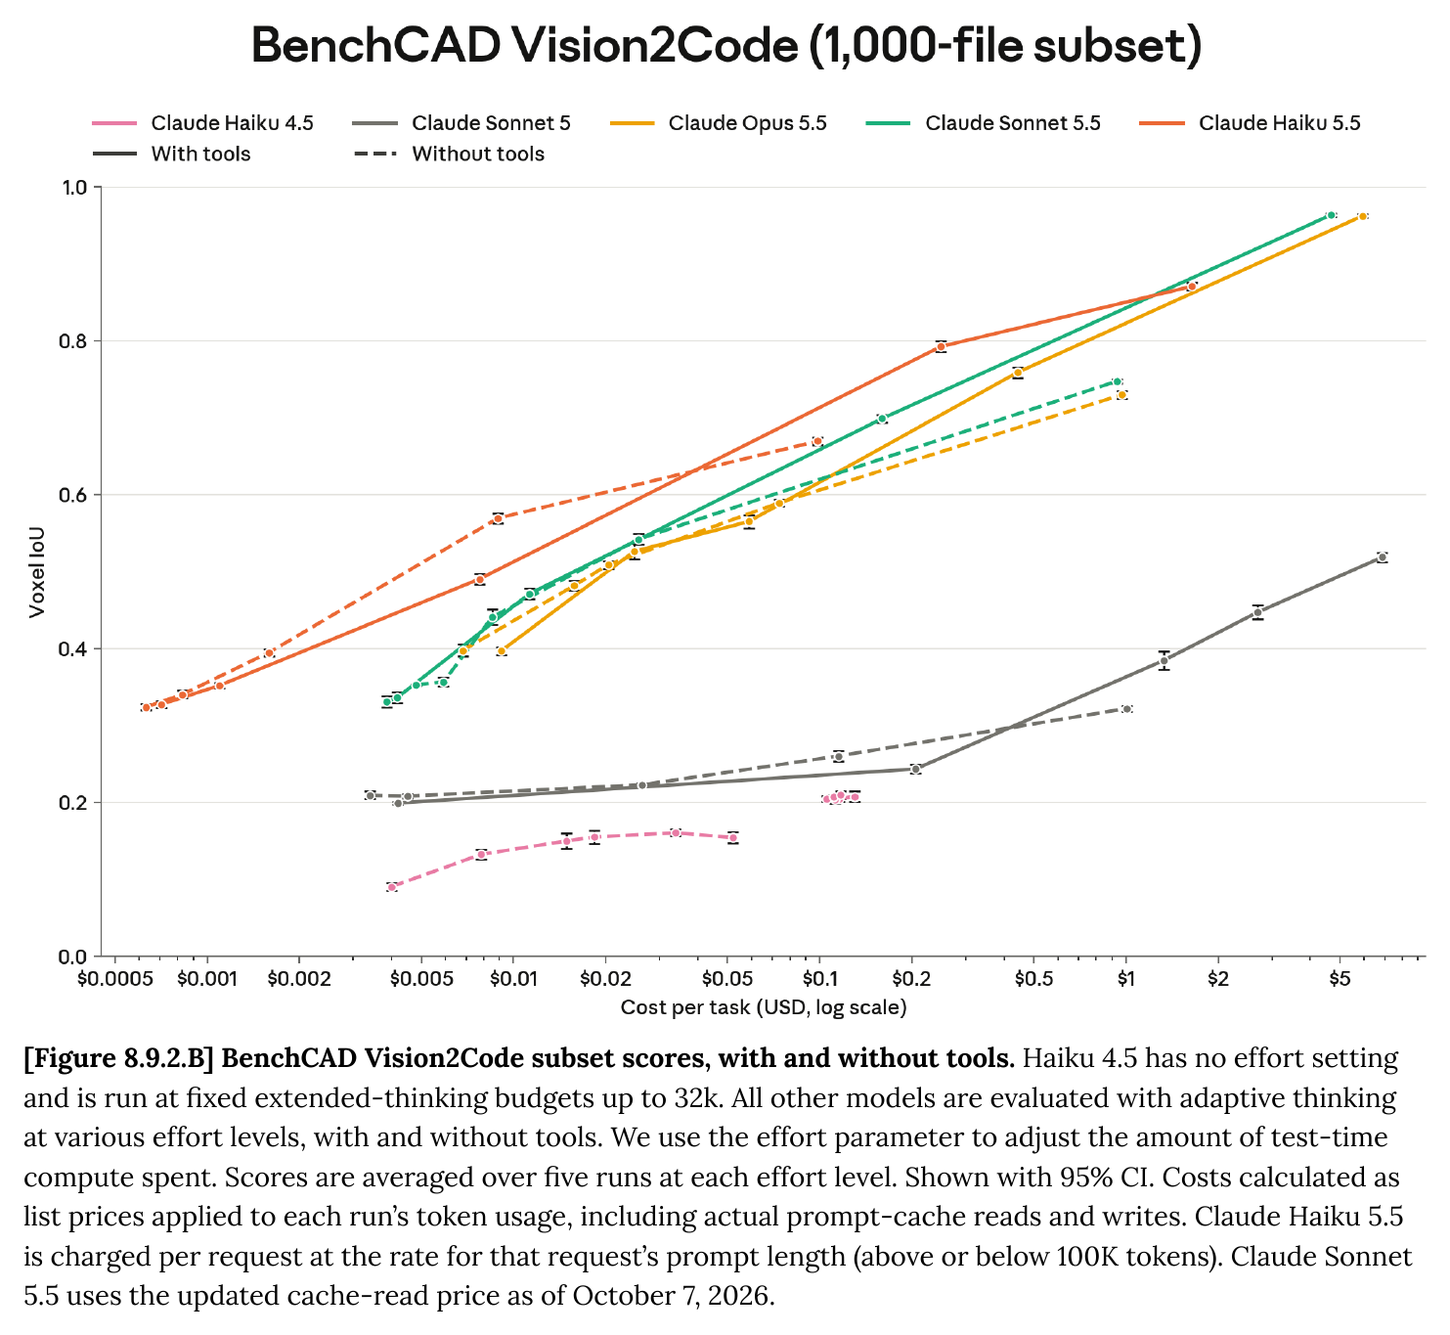
With tools, Haiku 5.5 reaches about 0.79 at roughly $0.25 a task, ahead of every other model in the card at that cost, and 0.870 at under $2.

BenchCAD Vision2Code voxel IoU vs cost per task on a log scale, with tools (solid) and without (dashed), for Claude Haiku 4.5, Sonnet 5, Opus 5.5, Sonnet 5.5 and Haiku 5.5. Haiku 5.5 with tools reaches about 0.79 at about $0.25 per task and 0.870 at under $2; without tools it reaches 0.670 at about $0.10.
read the system card
2026-09-28

Claude Sonnet 5.5 on BenchCAD: 0.963 with tools, 0.747 without

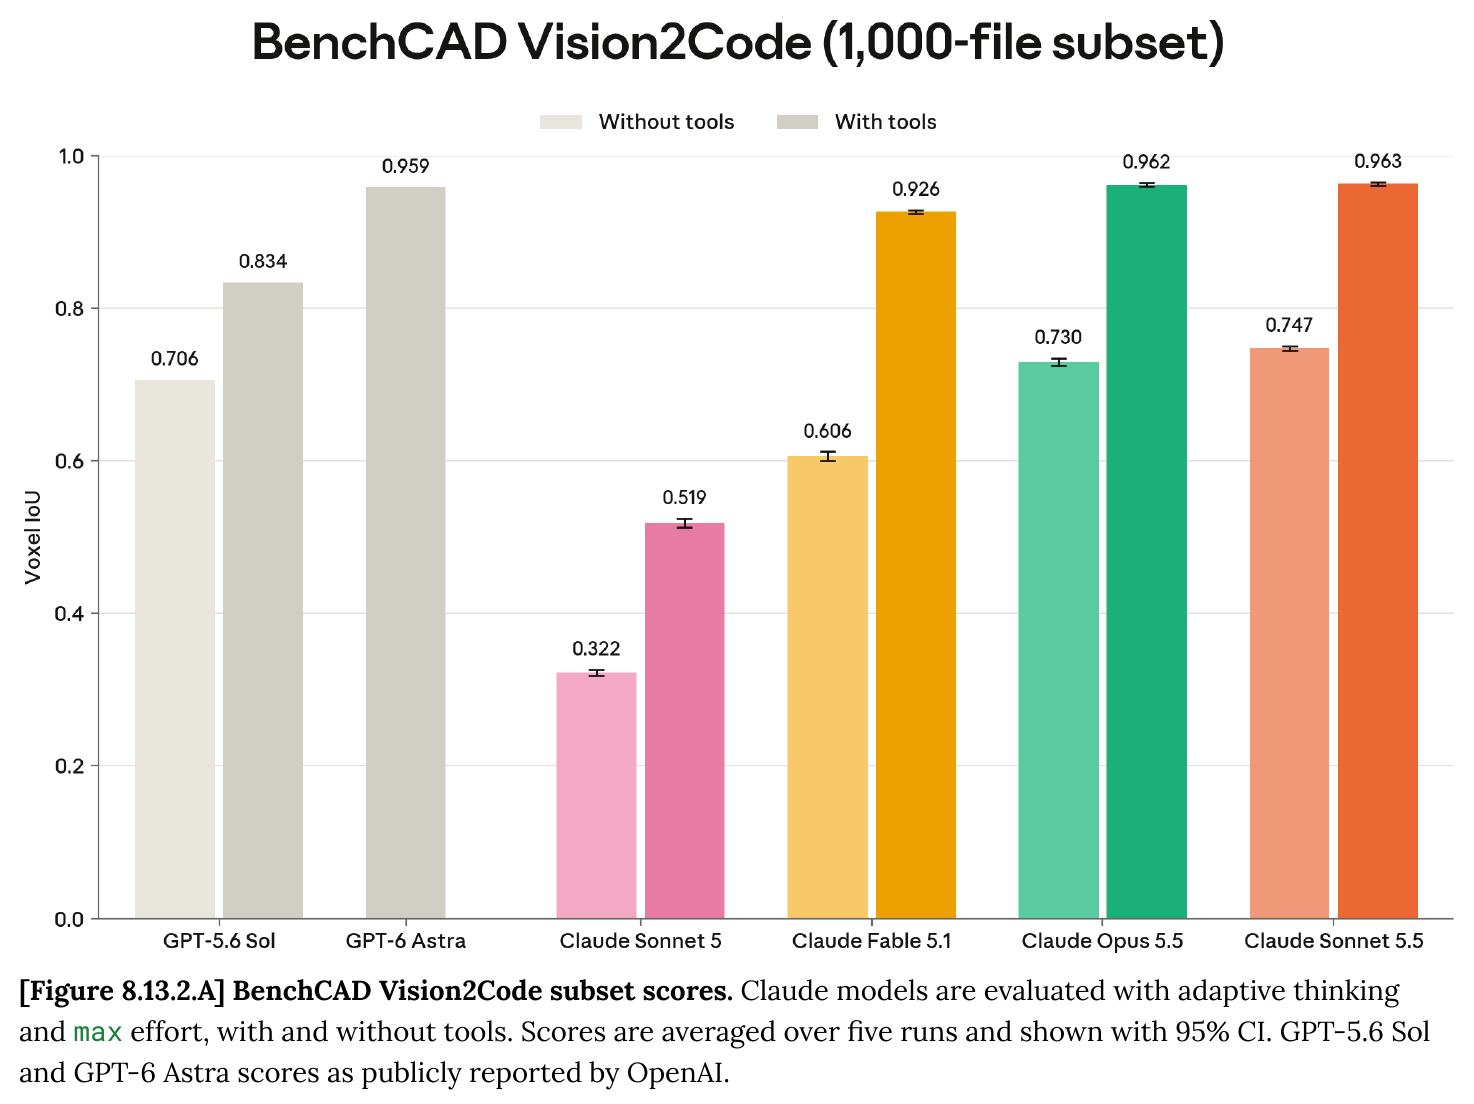
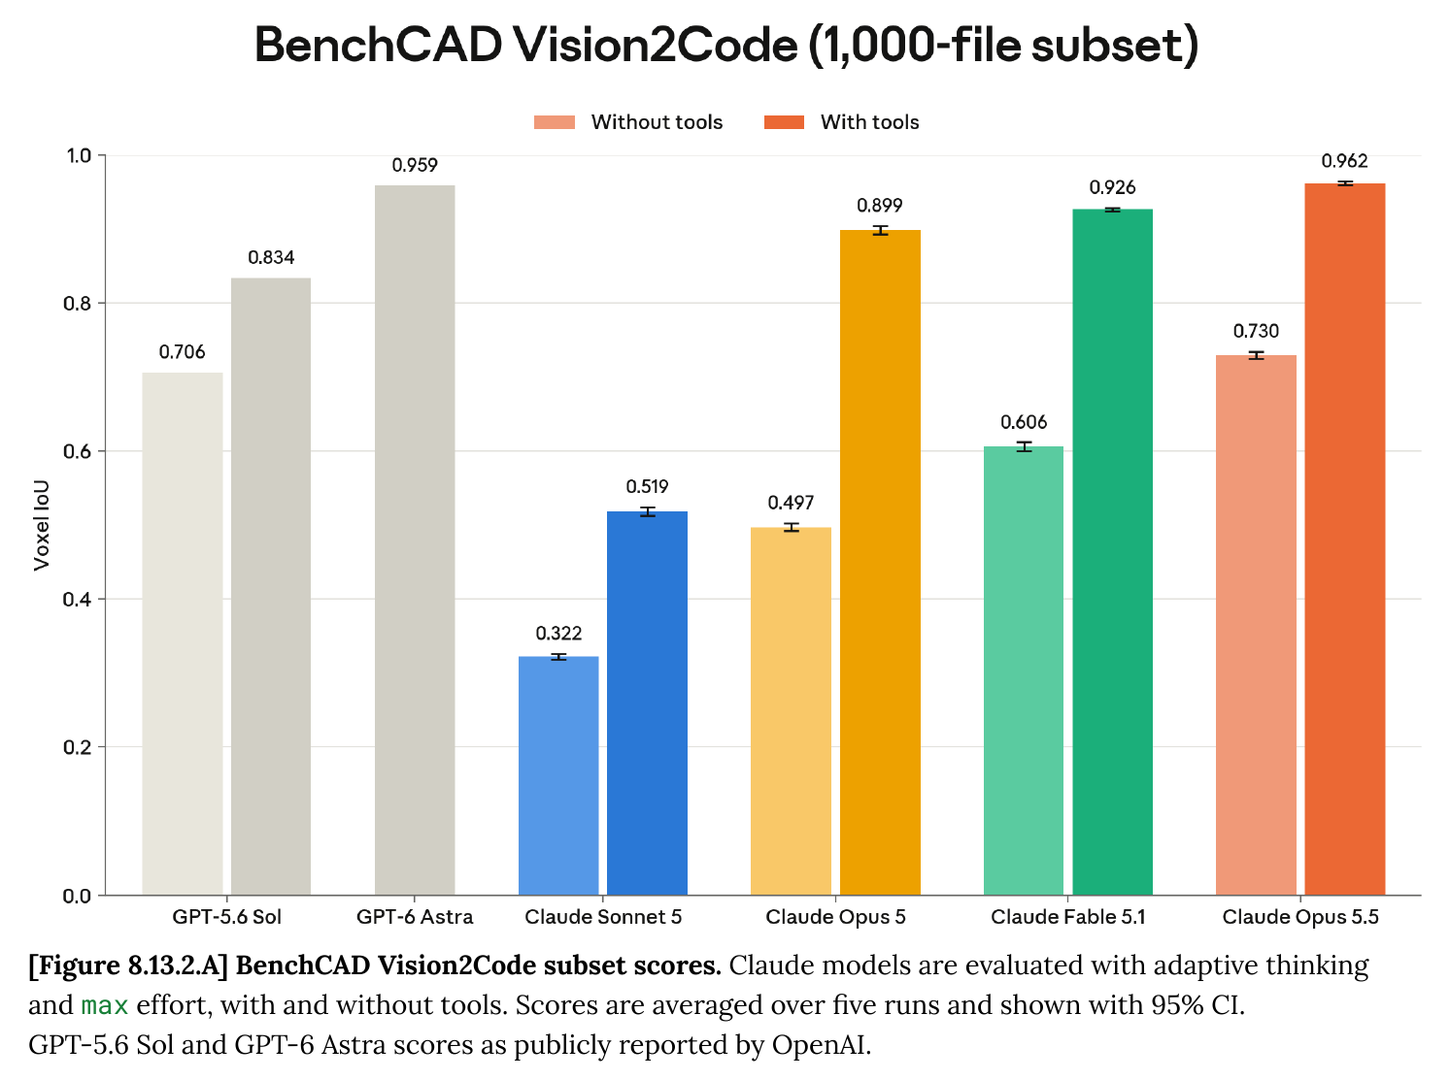
Anthropic's Sonnet 5.5 system card reports 0.963 with tools and 0.747 without on the 1,000-file Vision2Code subset: first in both settings on our leaderboard, just ahead of Opus 5.5 (0.962 / 0.730) and GPT-6 Astra (0.959 with tools). Congratulations to the Anthropic team!

BenchCAD Vision2Code ranking on 2026-09-28
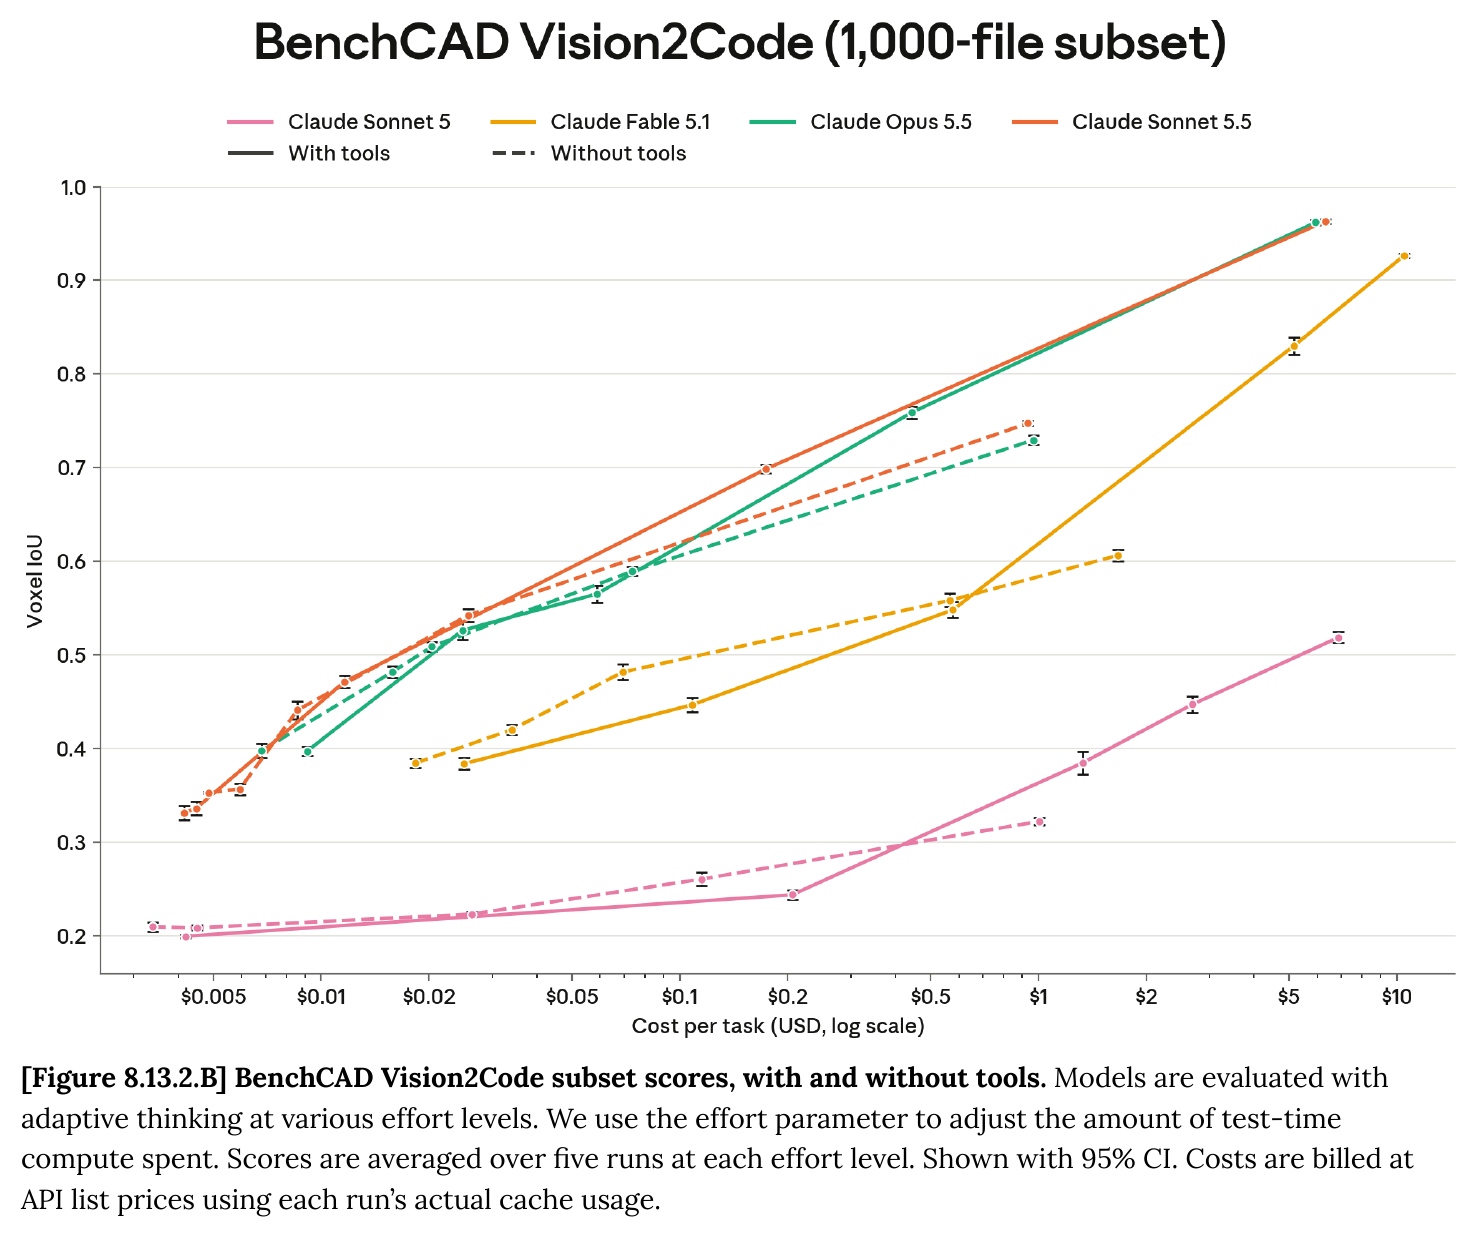
BenchCAD Vision2Code (1,000-file subset) voxel IoU, without tools vs with tools: GPT-5.6 Sol 0.706 / 0.834, GPT-6 Astra 0.959 with tools, Claude Sonnet 5 0.322 / 0.519, Claude Fable 5.1 0.606 / 0.926, Claude Opus 5.5 0.730 / 0.962, Claude Sonnet 5.5 0.747 / 0.963.

As in Opus 5.5's card, the score climbs with test-time compute, most steeply with tools: Sonnet 5.5 goes from about 0.33 at under half a cent a task to 0.963 at about $6.

BenchCAD Vision2Code voxel IoU vs cost per task on a log scale, with tools (solid) and without (dashed), for Claude Sonnet 5, Fable 5.1, Opus 5.5 and Sonnet 5.5. Sonnet 5.5 with tools reaches 0.963 at about $6 per task, level with Opus 5.5; without tools it tops out at 0.747 at about $1.
read the system card
2026-09-22

Claude Opus 5.5 on BenchCAD: 0.962 with tools, 0.730 without

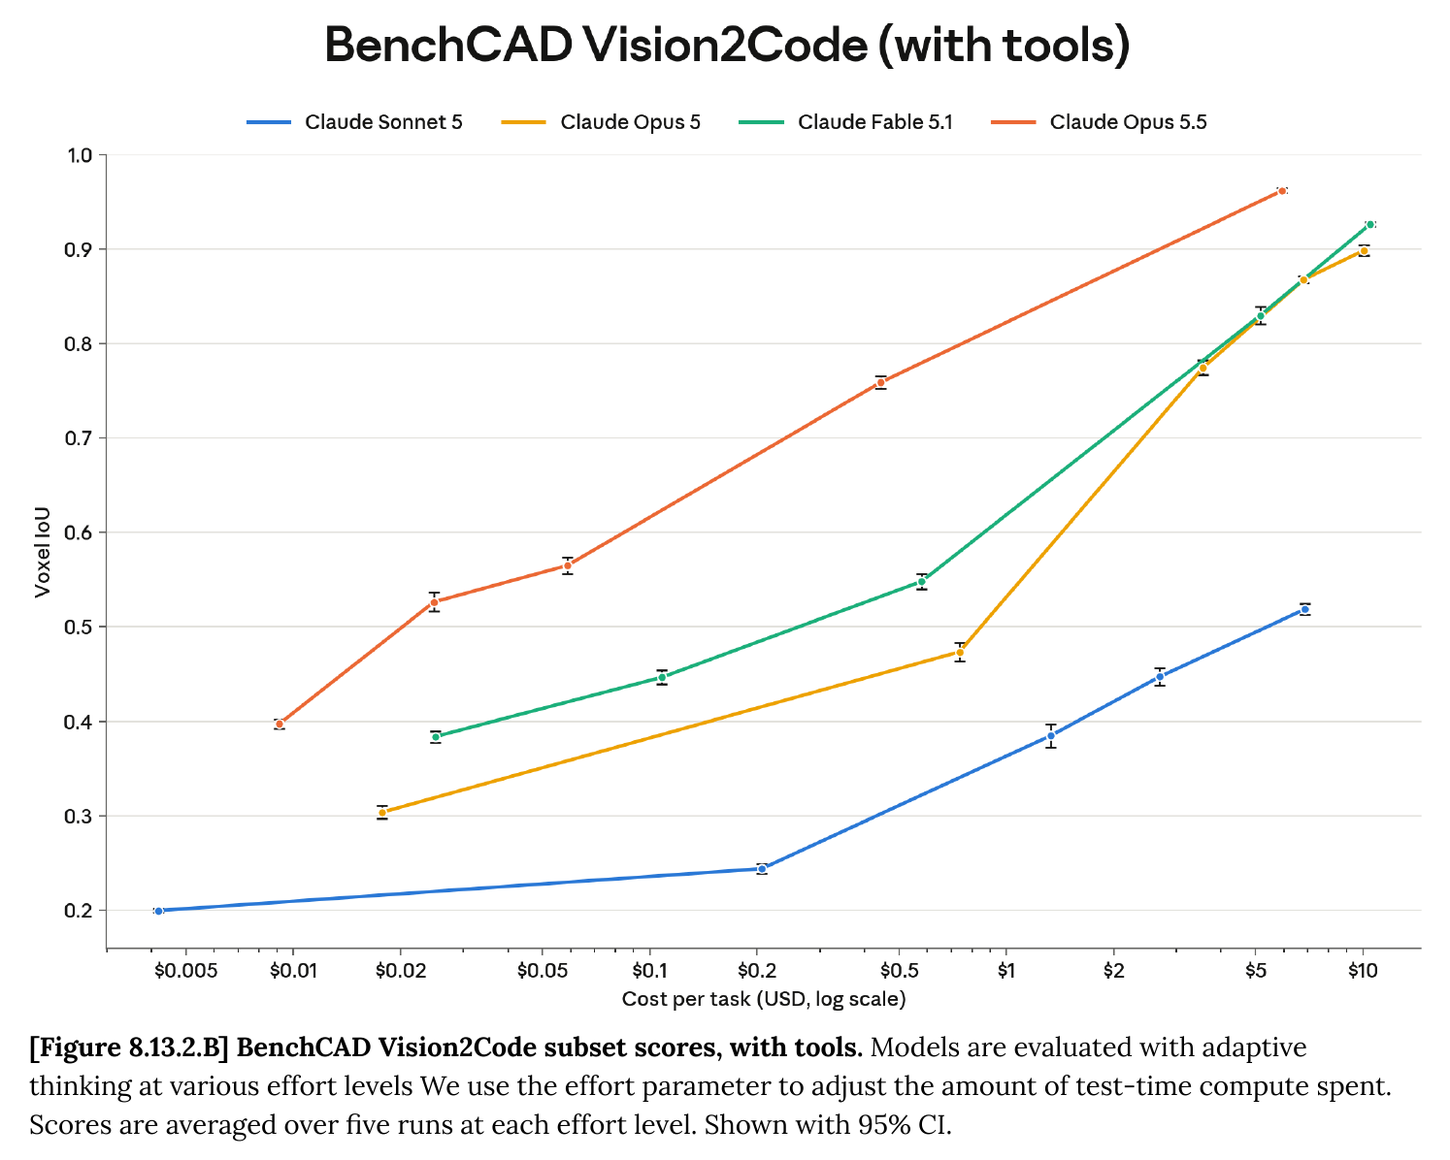
Anthropic's Opus 5.5 system card reports 0.730 without tools and 0.962 with tools on the 1,000-file Vision2Code subset, the highest score published in either setting.

BenchCAD Vision2Code ranking on 2026-09-22
BenchCAD Vision2Code (1,000-file subset) voxel IoU, without tools vs with tools: GPT-5.6 Sol 0.706 / 0.834, GPT-6 Astra 0.959 with tools, Claude Sonnet 5 0.322 / 0.519, Claude Opus 5 0.497 / 0.899, Claude Fable 5.1 0.606 / 0.926, Claude Opus 5.5 0.730 / 0.962.

The same card re-runs Anthropic's earlier models with each view rendered at 256 px, as the reference harness does; earlier cards had used 128 px views. Fable 5.1 is now 0.606 / 0.926 (was 0.437 / 0.843), Opus 5 0.497 / 0.899 (was 0.366 / 0.821) and Sonnet 5 0.322 / 0.519.

BenchCAD Vision2Code with tools, voxel IoU vs cost per task on a log scale, for Claude Sonnet 5, Opus 5, Fable 5.1 and Opus 5.5. Opus 5.5 reaches 0.962 at about $6 per task and sits above the other curves at every cost.
read the system card
2026-09-03

GPT-6 Astra on BenchCAD: 0.959 with tools

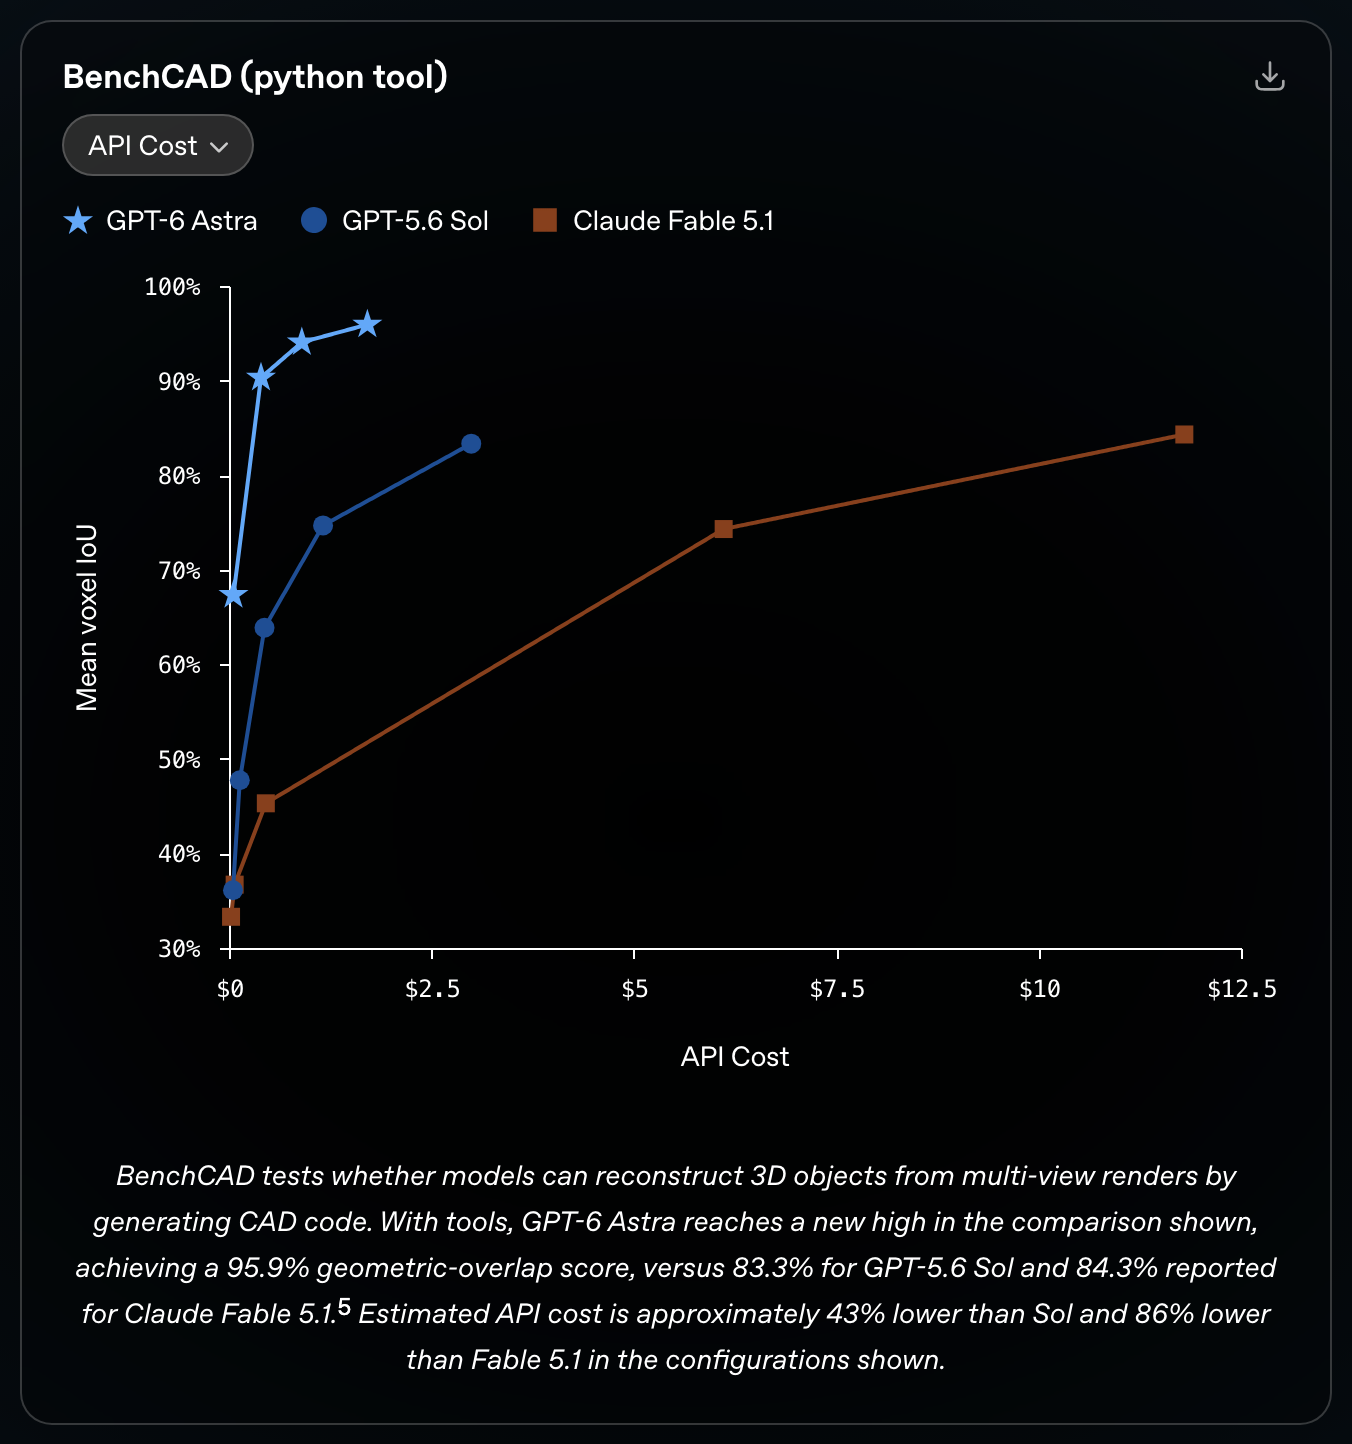
OpenAI's GPT-6 Astra launch lists BenchCAD at 0.959 with a Python tool on the 1,000-file Vision2Code subset — the second lead change in three days, after Claude Fable 5.1's 0.843 on September 1.

BenchCAD Vision2Code ranking on 2026-09-03
With tools
OpenAI's BenchCAD (python tool) chart from the GPT-6 Astra launch post: mean voxel IoU against API cost per task for GPT-6 Astra, GPT-5.6 Sol and Claude Fable 5.1. Astra reaches 95.9% at under $2, Sol 83.3% at about $3, Fable 5.1 84.3% at about $12.

Two caveats we are keeping visible. OpenAI has published no no-tools figure, so Astra carries an agentic score only and takes no rank in the plain column. And OpenAI notes its own Claude comparison runs “used modified evaluation settings” — the Claude numbers on our leaderboard come from Anthropic's system cards, not from OpenAI's table.

read the launch post the launch post on X
2026-09-01

Claude Fable 5.1 on BenchCAD: 0.843 with tools, 0.437 without

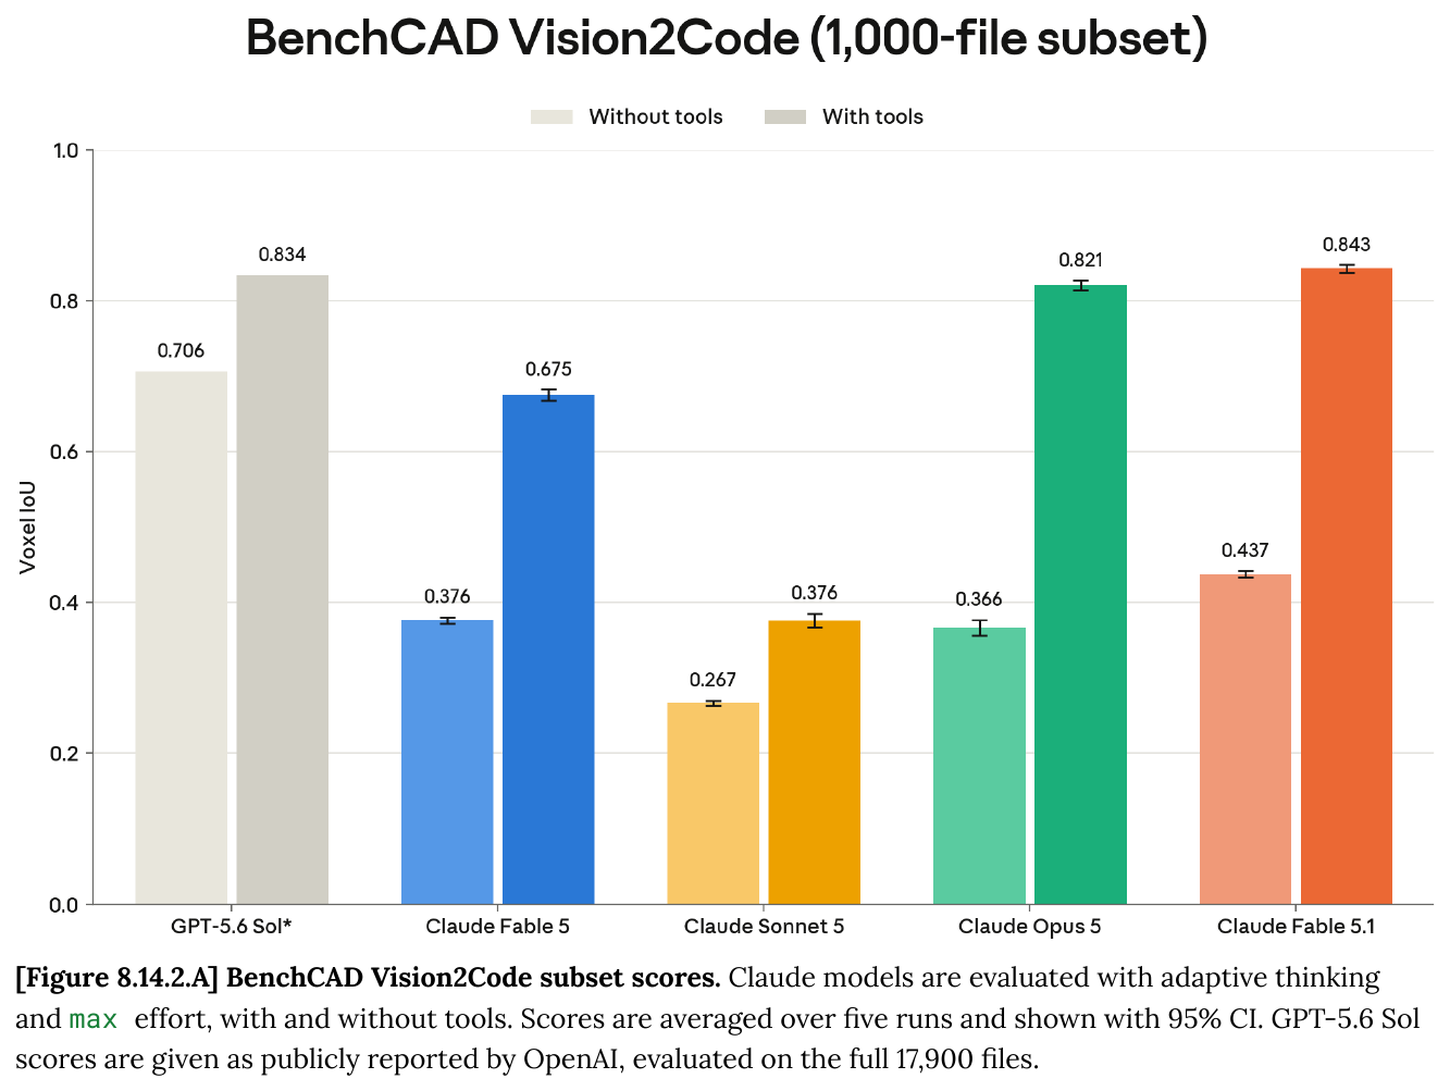
Anthropic's Fable 5.1 system card reports it on BenchCAD's Vision2Code subset — 0.437 without tools and 0.843 with, the highest with-tools score any lab has published, narrowly past GPT-5.6 Sol's 0.834.

BenchCAD Vision2Code ranking on 2026-09-01
BenchCAD Vision2Code (1,000-file subset) voxel IoU, without tools vs with tools: GPT-5.6 Sol 0.706 / 0.834, Claude Fable 5 0.376 / 0.675, Claude Sonnet 5 0.267 / 0.376, Claude Opus 5 0.366 / 0.821, Claude Fable 5.1 0.437 / 0.843.

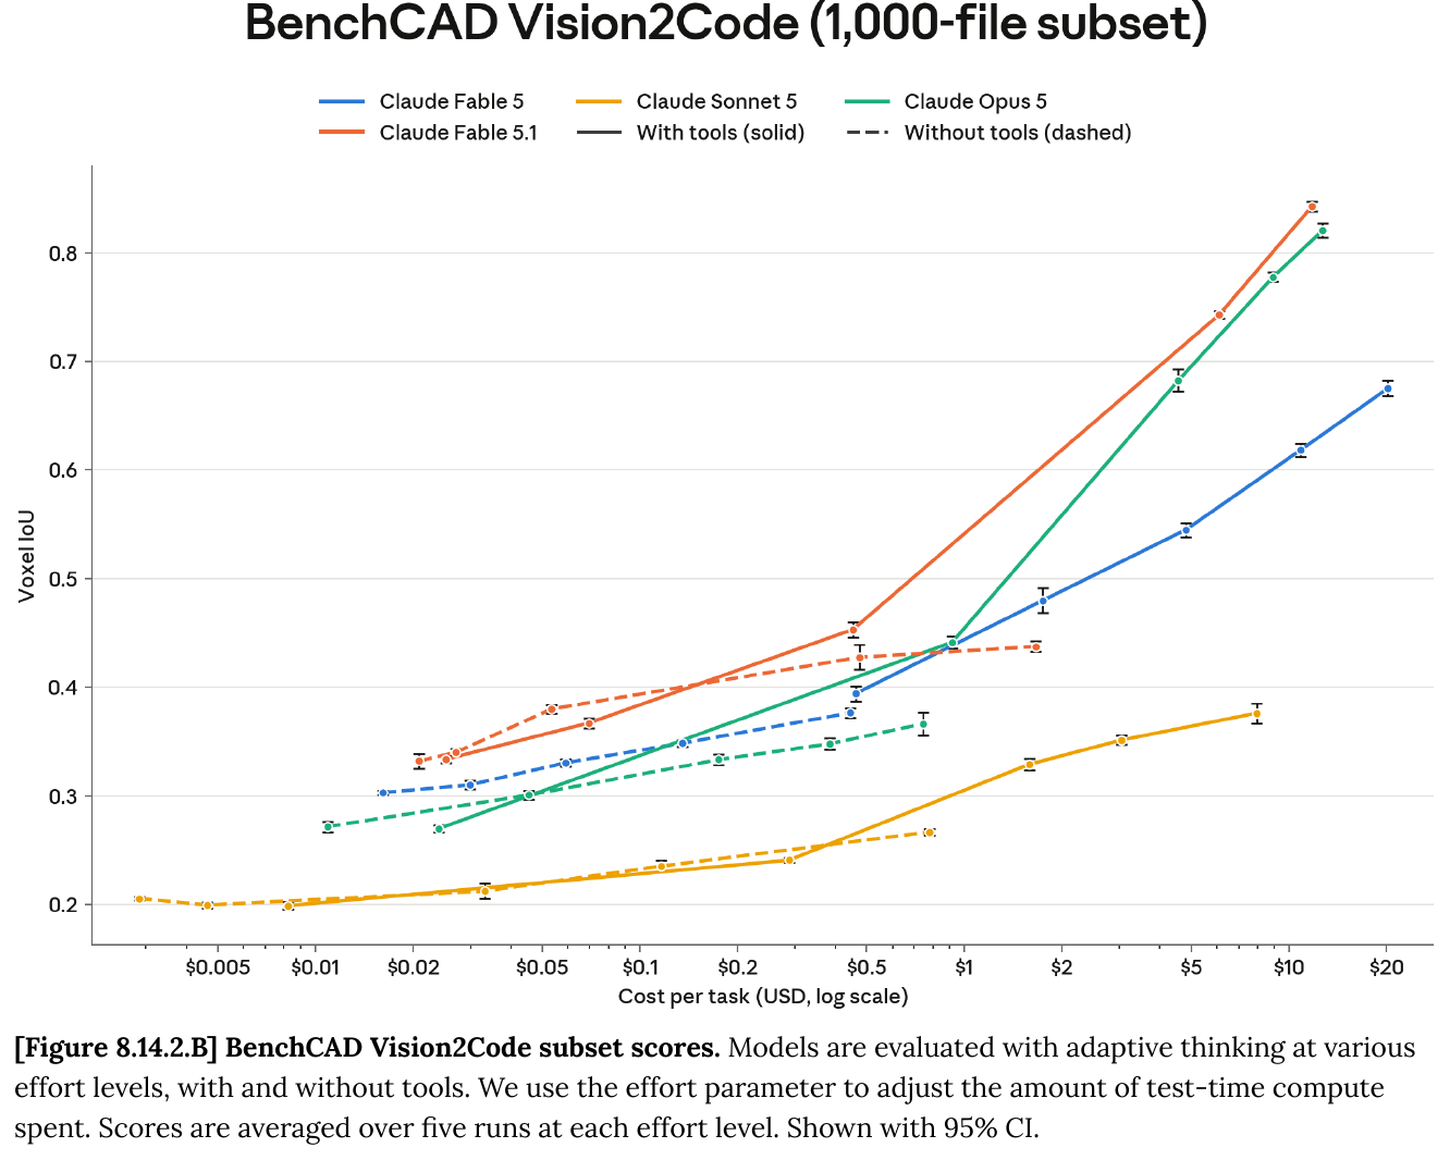
Without tools the order is unchanged — Sol still leads 0.706 to 0.437. The whole gain sits in the agentic setting, and it keeps scaling with test-time compute: with tools, Fable 5.1 nearly doubles its own no-tools score.

BenchCAD Vision2Code voxel IoU vs cost per task on a log scale, with tools (solid) and without (dashed), for Claude Fable 5, Sonnet 5, Opus 5 and Fable 5.1. Fable 5.1 with tools climbs to about 0.84 as test-time compute increases, while its no-tools curve flattens near 0.44.
read the system card
2026-07-24

Claude Opus 5 on BenchCAD: 0.821 with tools, 0.366 without

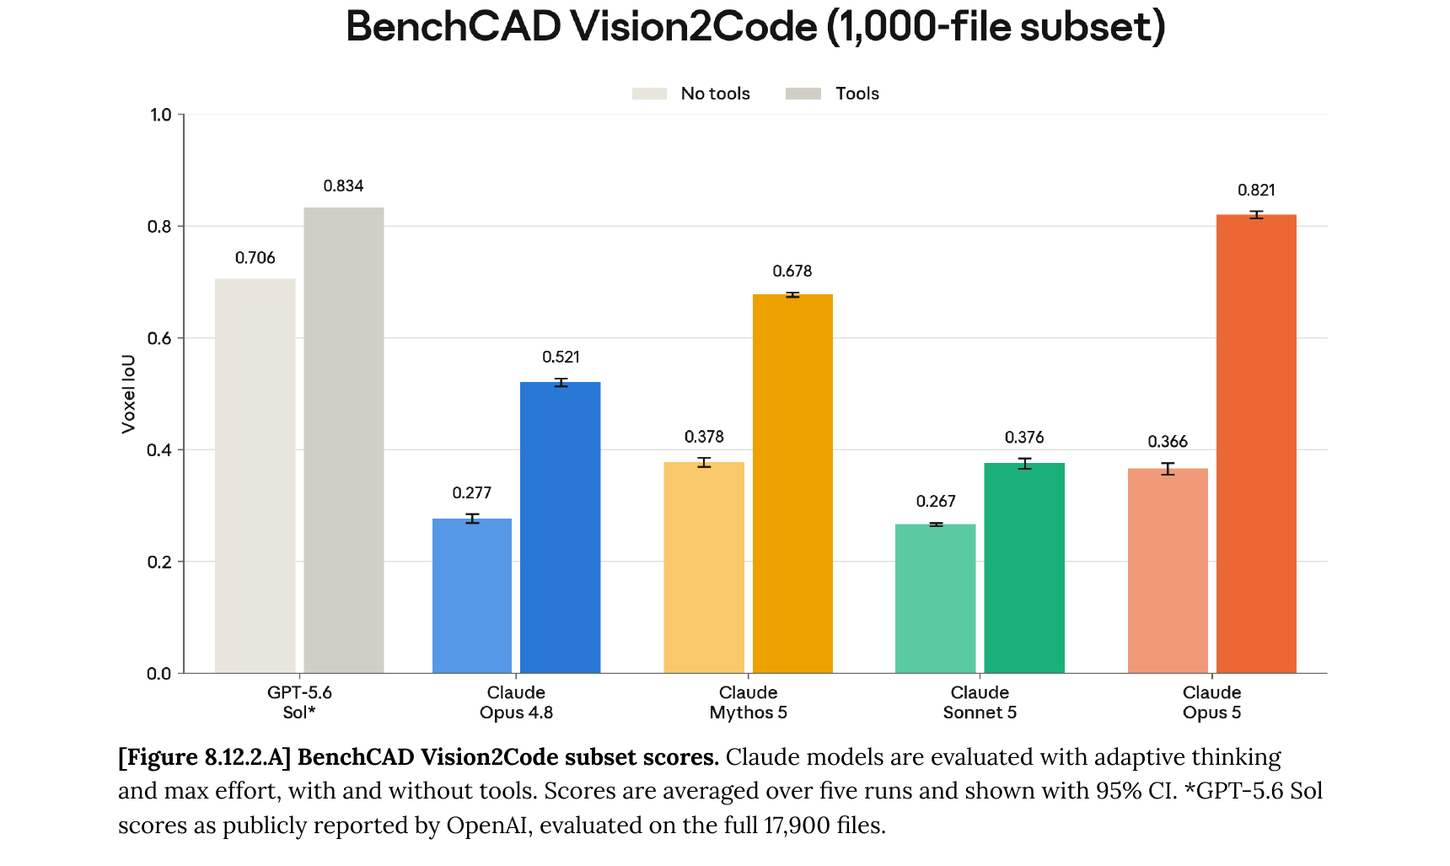
Anthropic's Opus 5 system card reports it on BenchCAD's Vision2Code subset — 0.366 without tools, 0.821 with — and it upstreams two fixes to our reference (a camera-position typo and raw-shape grading).

BenchCAD Vision2Code ranking on 2026-07-24
BenchCAD Vision2Code (1,000-file subset) voxel IoU, no-tools vs tools: GPT-5.6 Sol 0.706 / 0.834, Claude Opus 4.8 0.277 / 0.521, Claude Mythos 5 0.378 / 0.678, Claude Sonnet 5 0.267 / 0.376, Claude Opus 5 0.366 / 0.821.

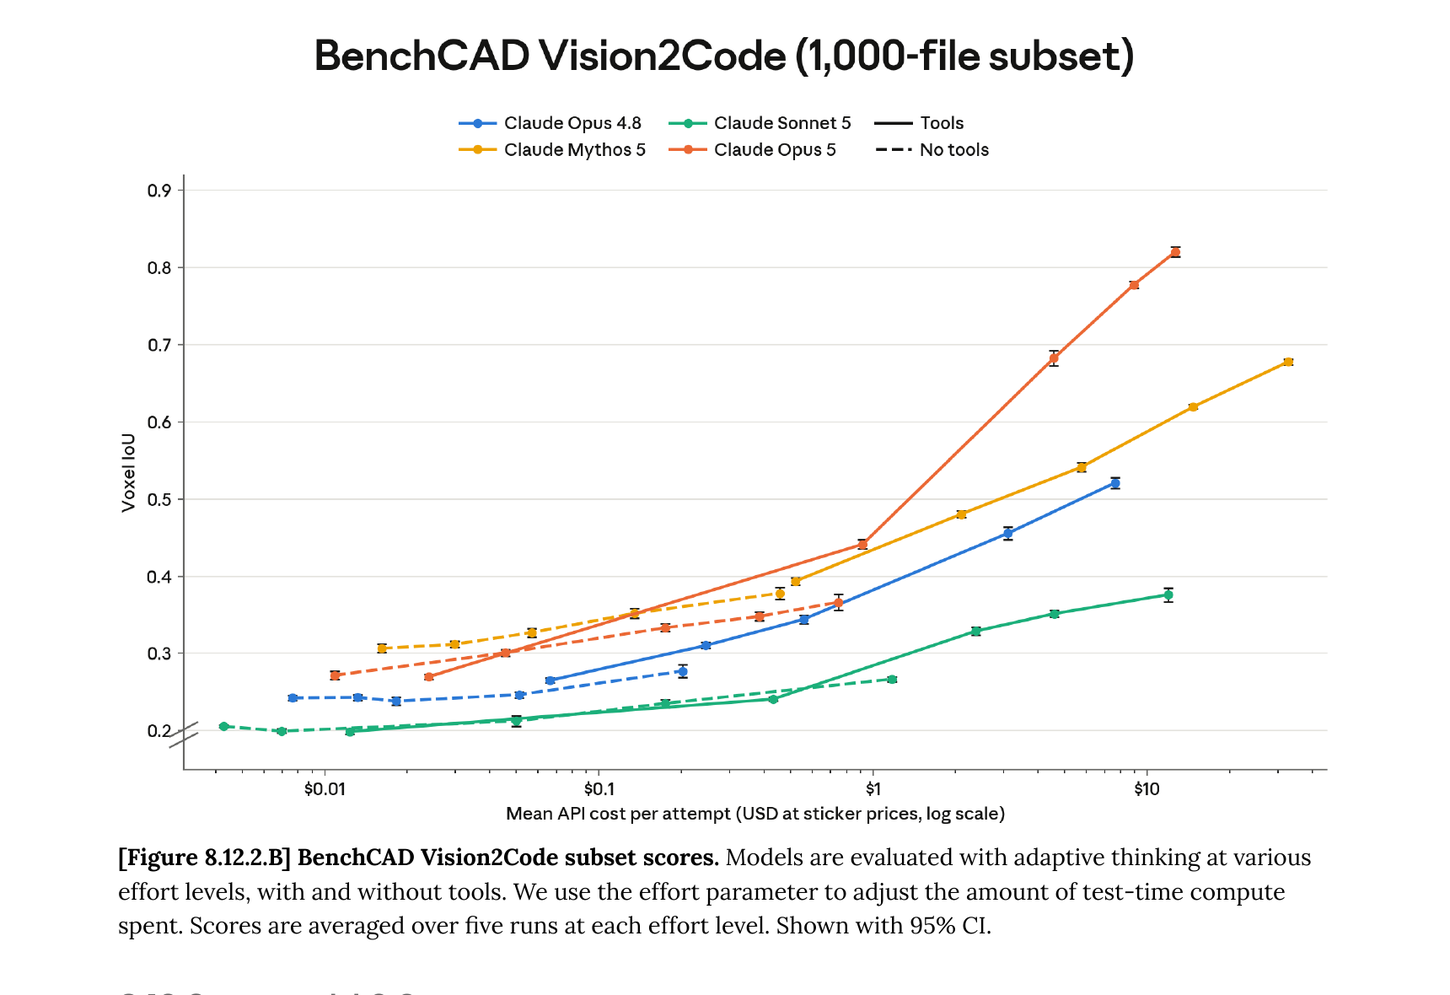
The story isn't the single number — it's the slope. On BenchCAD, Claude's scores now scale steeply with test-time compute, especially once the model has tools to crop and verify its own renders. More effort buys markedly more accuracy.

BenchCAD Vision2Code voxel IoU vs mean API cost per attempt on a log scale (test-time compute), with and without tools, for Claude Opus 4.8, Mythos 5, Sonnet 5 and Opus 5. Opus 5 with tools climbs from about 0.27 to 0.82 as test-time compute increases.

The card also re-runs Opus 4.8 (0.277 / 0.521), Mythos 5 (0.378 / 0.678 on the subset, where its own card had 0.379 / 0.650) and Sonnet 5 (0.267 / 0.376) on the same harness as Opus 5.

read the system card
2026-07-09

GPT-5.6 Sol on BenchCAD: 0.834 with tools, 0.706 without

OpenAI lists BenchCAD in its GPT-5.6 launch table, next to OSWorld and BrowseComp — the second frontier lab after Anthropic to report it in a flagship launch, and another sign AI for hardware is now a strategic front.

BenchCAD Vision2Code ranking on 2026-07-09
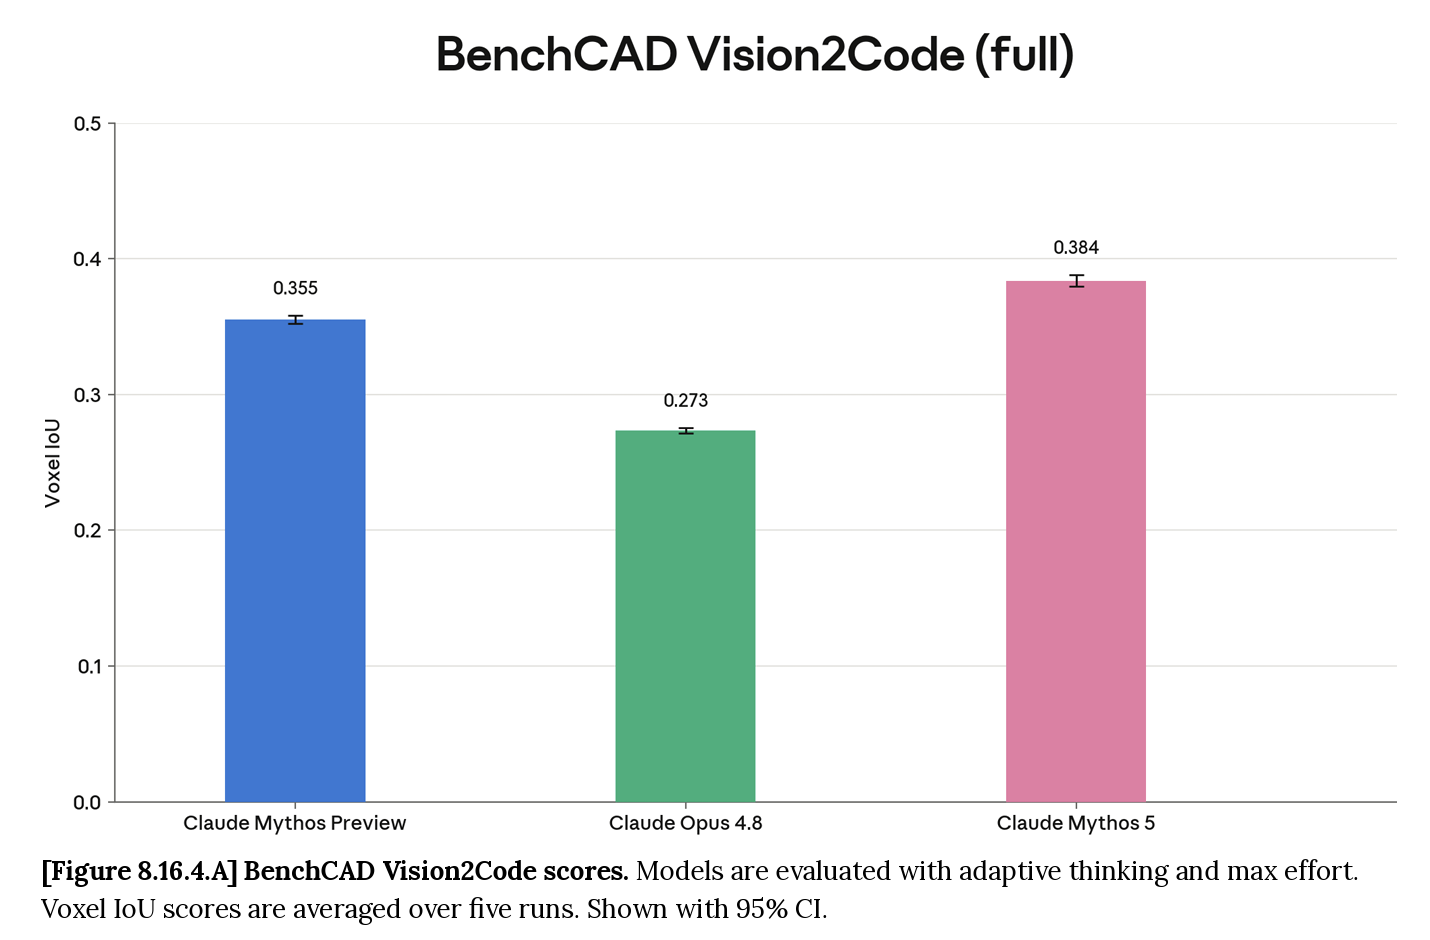
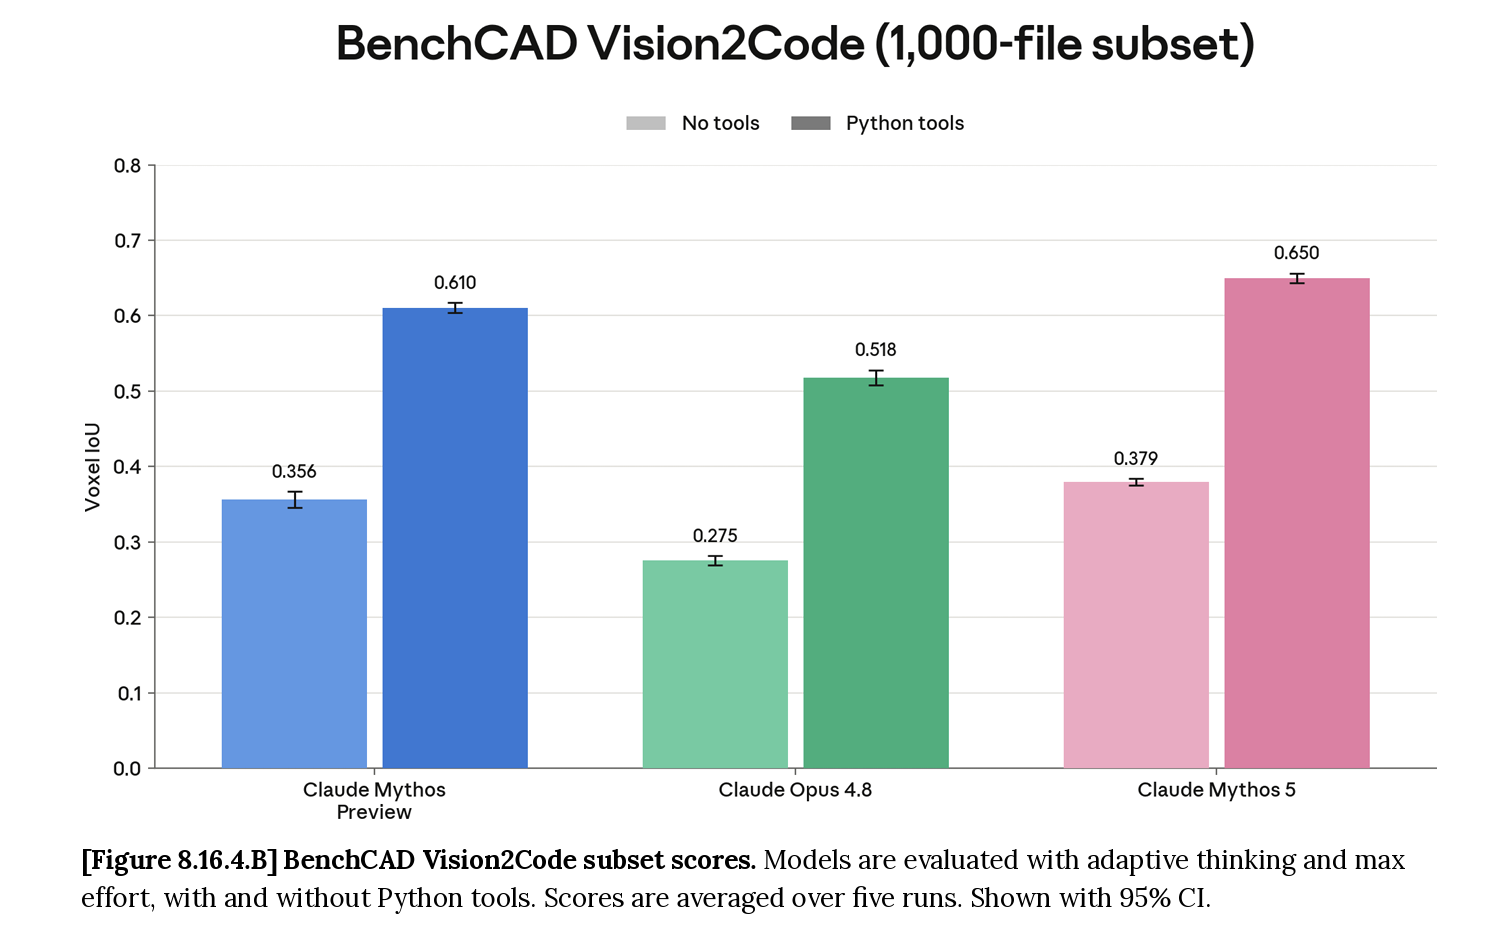
GPT · run by OpenAI Claude · Anthropic's own numbers, republished no tools Python tool GPT-5.6 Sol GPT-5.6 Luna GPT-5.6 Terra GPT-5.5 Mythos 5 Mythos Preview Opus 4.8 GPT-5.6 Sol · 70.6 — OpenAI launch table, no tools. Split, metric and attempt budget unstated. GPT-5.6 Luna · 63.1 — OpenAI launch table, no tools. Split, metric and attempt budget unstated. GPT-5.6 Terra · 62.3 — OpenAI launch table, no tools. Split, metric and attempt budget unstated. GPT-5.5 · 44.4 — OpenAI launch table, no tools (self-reported). Claude Mythos 5 · 38.4 = Anthropic's 0.384 voxel IoU on the FULL set (system card fig. 8.16.4.A) Claude Mythos Preview · 35.5 = Anthropic's 0.355 voxel IoU on the FULL set (system card fig. 8.16.4.A) Claude Opus 4.8 · 27.3 = Anthropic's 0.273 voxel IoU on the FULL set (system card fig. 8.16.4.A) GPT-5.6 Sol · 83.4 — OpenAI launch table, Python tool. Split, metric and attempt budget unstated. GPT-5.6 Luna · 73.9 — OpenAI launch table, Python tool. Split, metric and attempt budget unstated. GPT-5.6 Terra · 78.2 — OpenAI launch table, Python tool. Split, metric and attempt budget unstated. GPT-5.5 · 55.8 — OpenAI launch table, Python tool. Split, metric and attempt budget unstated. Claude Mythos 5 · 65 = Anthropic's 0.650 voxel IoU on the 1,000-file SUBSET (system card fig. 8.16.4.B) — a different split from the 38.4 beside it Claude Mythos Preview · 61 = Anthropic's 0.610 voxel IoU on the 1,000-file SUBSET (system card fig. 8.16.4.B) — a different split from the 35.5 beside it Claude Opus 4.8 · 51.8 = Anthropic's 0.518 voxel IoU on the 1,000-file SUBSET (system card fig. 8.16.4.B) — a different split from the 27.3 beside it 70.663.162.344.438.435.527.3 83.473.978.255.865.061.051.8

Scores exactly as printed in OpenAI's launch table (computer-use section, 2026-07-09), self-reported voxel IoU. The Claude bars are Anthropic's own published figures, republished by OpenAI. Hover any bar for its source and split.

read the launch post the re-graded leaderboard
2026-06-30

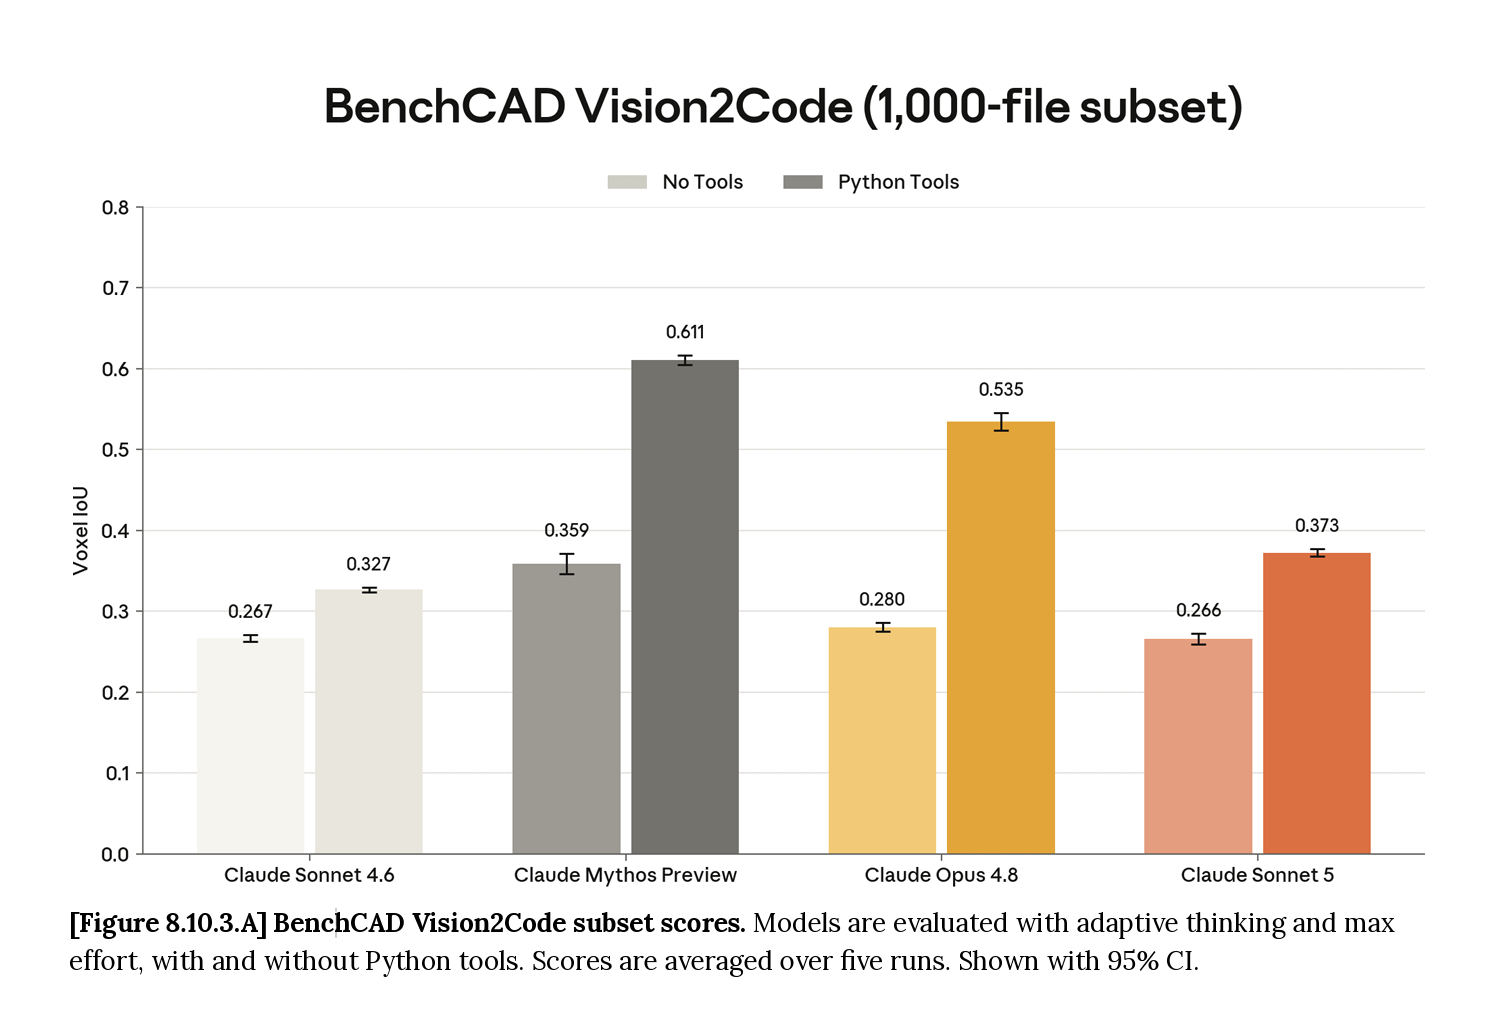
Claude Sonnet 5 on BenchCAD: 0.373 with tools, 0.266 without

Anthropic's Sonnet 5 system card reports it on BenchCAD's Vision2Code subset — 0.266 without tools, 0.373 with — another flagship model card measuring on the benchmark.

BenchCAD Vision2Code ranking on 2026-06-30
BenchCAD Vision2Code (1,000-file subset) voxel IoU, no-tools vs Python-tools: Claude Sonnet 4.6 0.267 / 0.327, Claude Mythos Preview 0.359 / 0.611, Claude Opus 4.8 0.280 / 0.535, Claude Sonnet 5 0.266 / 0.373.

The card also re-runs Opus 4.8 (0.280 / 0.535) and Mythos Preview (0.359 / 0.611): the Fable 5 / Mythos 5 card had applied only the camera-prompt fix, and these are the first scores with the raw-shape grading fix in place too.

read the system card
2026-06-10

Claude Mythos 5 on BenchCAD: 0.650 with tools, 0.384 without

Anthropic's Claude Fable 5 / Mythos 5 system card evaluates on BenchCAD Vision2Code: their strongest model reaches ~0.38 voxel IoU on the full set, and ~0.65 with Python tools on a 1,000-file subset. The first frontier lab to fold execution-grounded CAD into how it measures its models — an early marker of what has since become a strategic front.

BenchCAD Vision2Code ranking on 2026-06-10
Anthropic system card figure — BenchCAD Vision2Code (full): Claude Mythos Preview 0.355, Claude Opus 4.8 0.273, Claude Mythos 5 0.384 voxel IoU Anthropic system card figure — BenchCAD Vision2Code (1,000-file subset): no-tools vs Python-tools voxel IoU for Claude Mythos Preview, Claude Opus 4.8, Claude Mythos 5
read the system card