
BenchCAD is a benchmark for multimodal models. The task is simple to state: look at a mechanical part and write the CAD code that rebuilds it. Doing it well takes the whole multimodal stack at once: reading the views, tying them to text and code, reasoning about the shape in 3D, and recovering the exact numbers.
Two programs can build parts that look the same and still differ in a dimension, a hole or a symmetry. So every answer is run, and the solid it builds is checked against the real part. A part can pass the eye and still fail the caliper.
What it measures
Four properties make BenchCAD a clean test of multimodal spatial reasoning:
- Execution-verified at scale. 17,900 CadQuery parts across 106 industrial families, each one executed in a sandbox.
- Grounded in real parts. About half the families (52 of 106) follow ISO, DIN, EN, ASME or IEC standards; the rest follow common engineering practice.
- Spatially rich. The programs use 46 CadQuery operations, such as rotations, arrays, sweeps, lofts and helices, that need real 3D reasoning.
- Split by capability. Four matched tasks, Vision2Code, Vision QA, Code QA and Code Edit, separate perception, image-to-code grounding, numeric reasoning and code synthesis.
Three datasets
Every family was built by hand by domain experts, from industrial standards.
| Dataset | What it holds | Items |
|---|---|---|
| BenchCAD | Verified CadQuery parts, each with its code, STEP file, four canonical views, parameters and operation trace | 17,900 |
| BenchCAD-QA | Paired image and code questions with numeric answers, along a four-level capability hierarchy | 2,400 |
| BenchCAD-Edit | Verified before and after pairs across five kinds of edit, T1 to T5 | 748 |

Figure 2. The 106 part families: fasteners, transmission, structural, fluid, panels, hardware and enclosures. About half (52 of 106) sample from real specification tables across 47 ISO, DIN, EN, ASME and IEC codes; the rest are common engineering parts.
A capability hierarchy
The same questions are asked twice: once over the renders (Vision QA) and once over the source code (Code QA). The matched pair exposes a gap between the two, which tells a failure of visual perception apart from a failure of parametric reasoning. CAD errors are often compositional: the right family but the wrong operation, or the right scale but the wrong relation between standard dimensions.
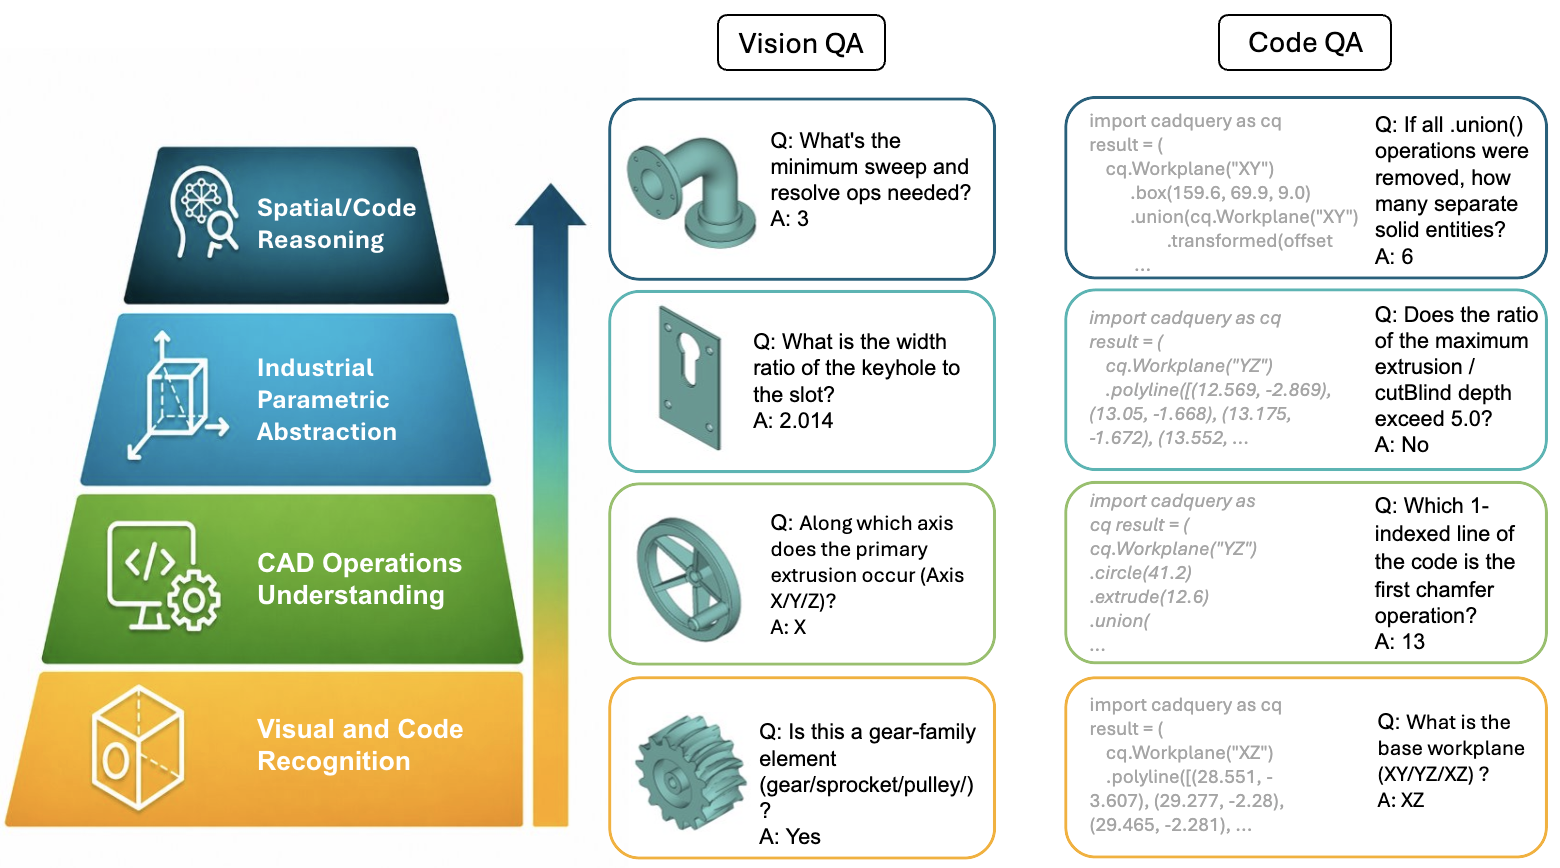
Figure 3. The four levels: L1 holistic visual recognition, L2 CAD operation understanding, L3 industrial parametric abstraction and L4 compositional spatial and code reasoning.
How we score
Scoring is grounded in execution. A generated program is run, and the solid it builds is compared with the reference by IoU; the questions are scored by ratio accuracy.
Use BenchCAD 1.0
- Code and evaluation: BenchCAD-main on GitHub.
- Data: BenchCAD on Hugging Face. The dataset ships with Croissant 1.0 metadata; the code is MIT and the data CC-BY-4.0.
- Results: the leaderboard.
Citation
@misc{benchcad2026,
  title        = {BenchCAD: A Comprehensive, Industry-Standard Benchmark for Programmatic CAD},
  author       = {Zhang, Haozhe and Liu, Kaichen and Chen, Miaomiao and Li, Lei
                  and Yang, Shaojie and Peng, Cheng and Chen, Hanjie},
  year         = {2026},
  eprint       = {2605.10865},
  archivePrefix= {arXiv},
  primaryClass = {cs.CV},
  url          = {https://arxiv.org/abs/2605.10865}
}